What Operations Did Before: Runbooks, ITIL, DevOps, SRE and AIOps
This chapter describes how IT operations organised itself before AI took part in it. The baseline matters because every claim of later chapters about what AI changes is a claim about a difference, and a difference cannot be stated without the thing it differs from. The chapter concerns all five operations functions defined in Chapter 4: O1 Observe, because the first reliability practices were ways of deciding what to look at; O2 Diagnose, because the runbook and the incident review are older than any model; O3 Change, because the change advisory board and the deployment pipeline are rival answers to the same risk; O4 Restore, because scripted remediation has a long history before agents; and O5 Sustain, because toil, capacity and learning were named and measured before AI could do any of them.
Six operating models are described: the system administrator with a runbook, service management, DevOps, site reliability engineering (SRE), platform engineering and the first generation of AIOps, the application of machine learning to operational data. For each the chapter asks what it got right and which scarcity it answered. The second question is the book's own reading and is stated as such: each model took its shape from something that was in short supply, whether expert time, knowledge of what had changed, flow between teams, reliability engineering skill or attention to signals. A practice outlives the scarcity that produced it, and AI loosens several of those scarcities at once. Knowing which one a practice answered tells the reader what to keep, what to automate and what to retire.
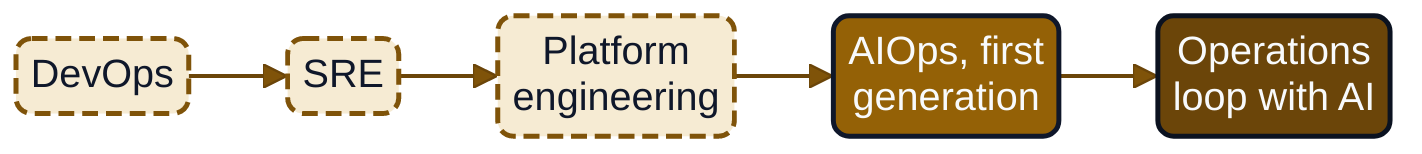
Figure 2.1: The lineage of operating models from DevOps to the operations loop with AI, The table below gives the scarcity each answered, including the two earlier models, the sysadmin with runbooks and service management.
The table gives every stage in the lineage and the scarcity it answered.
| Operating model | Scarcity it answered |
|---|---|
| Sysadmin and runbooks | Expert time |
| Service management | Knowledge of change |
| DevOps | Flow between teams |
| Site reliability engineering | Reliability engineering |
| Platform engineering | Attention of product teams |
| First-generation AIOps | Attention to signals |
| Operations loop with AI | The operator as accountable conductor |
A lineage of operating models
The six models are not strictly successive. They overlap in any real organisation, and most estates run several at once. The order below follows the order in which each became a recognised way of organising the work, and the table at the end of this section puts them side by side.
The system administrator and the runbook
The earliest model needs little description because the others are defined against it. A system administrator, or a small team of them, assembles existing software, runs it and repairs it. Knowledge of how the estate behaves sits in people and in documents they write, of which the runbook is the standard form: a procedure that says what to check and what to do when a particular condition arises. Benjamin Treynor Sloss, who founded Google's SRE function, described the sysadmin approach as one that assembles existing software and has administrators run it, with development and operations in separate teams. He noted that its direct costs are plain, because the size of the operations team grows with the load the system generates, and that its indirect costs can be larger, because separate teams with separate incentives drift into conflict and mistrust (112, Beyer et al., 2016).
The scarcity that shaped this model is expert time at the console. Everything about it follows: the runbook is a way of storing an expert's judgement where a less experienced person can use it at three in the morning; the on-call rota is a way of spreading scarce attention across the clock; and the ticket queue is a way of ordering demands that exceed what the experts can do.
Service management: ITIL and ISO/IEC 20000-1
Service management answered a different scarcity, which was knowledge of what was being changed and what depended on what. As estates grew, an administrator's memory stopped being a sufficient configuration database, and outages followed from changes that nobody had set against the dependencies. The best-known framework of practices for this is ITIL. Its characteristic artefacts are the incident, problem and change records, the configuration database, the service catalogue and the change advisory board (CAB), a forum that reviews significant changes before they are made. These are the artefacts that the two organisations of this book still carry in ServiceFlow and ServiceHub.
The international standard for the management system behind such practices is ISO/IEC 20000-1:2018, published on 14 September 2018 as its third edition. It sets requirements for an organisation to establish, implement, maintain and continually improve a service management system, covering the planning, design, transition, delivery and improvement of services (48, ISO/IEC, 2018). The standard is a requirement for a management system that an auditor can assess. It does not prescribe a particular tool, and its importance for this book is that it is a form in which an organisation can show an auditor that operations is controlled.
DevOps and the research on delivery
DevOps answered scarcity of flow. When development and operations were separate teams, each change passed through a hand-over, and the hand-over was where delay and error collected. DevOps joined the two concerns, with shared ownership, automated build and release, and fast feedback from production. Its research base is unusual for the field. Forsgren, Humble and Kim (2018) reported the statistical work of the DevOps Research and Assessment programme on what drives software delivery performance (267, Forsgren et al., 2018), and the programme's 2019 report summarised six years of survey data from over 31,000 professionals. It describes software delivery performance in four measures: deployment frequency and lead time for changes, which capture throughput, and time to restore service and change fail rate, which capture stability (113, Forsgren et al., 2019). Chapter 20 returns to these four key metrics, to how they are defined and to how they are misused. The point for this chapter is that DevOps put numbers on delivery, as measures of the delivery process.
Site reliability engineering
SRE answered scarcity of reliability engineering. Treynor Sloss gives the origin as a "Production Team" of seven engineers that he ran at Google from 2003, designed as he would want a software engineer's operations team to work, and describes SRE as what happens when a software engineer is asked to design an operations team (112, Beyer et al., 2016). Four ideas from this model are carried through the book. A service has a service level objective (SLO), a reliability target measured with service level indicators (SLIs), and the target is deliberately below 100 per cent. The gap between the target and perfection is an error budget that product and reliability teams spend together. Operational work, called toil, is capped, so that engineering time is kept for removing its causes. And an incident review is blameless: it asks what contributed to the failure, not who failed.
Platform engineering
Platform engineering answered scarcity of attention among product teams. As the supporting infrastructure of a cloud estate grew, product teams were forced to spend more time on it than on the product. The Cloud Native Computing Foundation's platforms white paper describes a platform as an integrated collection of capabilities defined and presented according to the needs of its users, and a platform team as responsible for the interfaces to and experiences with those capabilities. It identifies the pull of infrastructure concerns on product teams as the problem that platforms address (273, CNCF TAG App Delivery & Platforms Working Group, n.d.). Team Topologies gives the organisational form, with the platform team as one of four fundamental team types and X-as-a-Service as one of three interaction modes between teams (116, Skelton & Pais, 2025). Architecture as Code (Chapters 17 and 18) reached the same conclusion for the architecture function: platform teams act as internal service providers that own common toolchains, guardrails and reusable modules, and the design of a system mirrors the communication paths of the organisation that builds it (295, Nordqvist, 2025). The second point is Conway's: organisations that design systems are constrained to produce designs that are copies of the communication structures of those organisations (271, Conway, 1968).
A second lineage: from scripts to state engines
Running through the six models is a lineage of technique, which matters because it decides how much of the loop a machine already closes before any AI takes part. It moves from describing steps to describing a state, and from running on a person's command to running continuously.
The runbook and the script describe steps: what to check and what to do, in order. The result of a script depends on the state it starts from. Configuration-management tools moved the description towards the end state. The Ansible glossary defines an operation as idempotent if performing it once gives exactly the result of performing it repeatedly, and says the tool brings the system back to a desired state regardless of the actual state, instead of the user saying how to get there (294, Ansible project, n.d.). A person or a scheduler still decides when to run it.
Kubernetes made the comparison continuous. Burns and colleagues, engineers at Google, describe the lessons of a decade with three container management systems, Borg, Omega and Kubernetes. They report that every Kubernetes object has a Spec, which describes the desired state, and a Status, which gives read-only information about the current state; that the idea of a reconciliation controller loop is shared throughout the three systems; and that such a loop compares a desired state with the observed state and takes actions to converge them. Because all action is based on observation rather than on a state diagram, they write, reconciliation loops are robust to failures and perturbations, and a controller that fails or restarts simply picks up where it left off (293, Burns et al., 2016). Kubernetes documents a controller as a non-terminating control loop that moves current state towards desired state (153, The Kubernetes Authors, n.d.), and its API conventions state that the system's behaviour is level-based rather than edge-based, which gives robust behaviour when intermediate changes are missed (175, Kubernetes SIG Architecture, n.d.). A controller does not need to have seen a change in order to correct the difference.
GitOps put the declaration in version control and named the pattern. The OpenGitOps principles, version 1.0.0, require desired state to be declarative, versioned and immutable, pulled automatically by software agents, and continuously reconciled against observed state (55, OpenGitOps, n.d.). Both organisations sit at this end of the lineage in their own way: Nordvik Region declares infrastructure in Git and applies it through a pipeline, and Hansa Mutual's production change runs through a GitOps pipeline.
The book's reading, which is its interpretation and not a finding of these sources, is that each step moved the loop from the person to the engine: from the person who runs the steps, to the tool that converges when asked, to the controller that converges all the time. The state engine already closes loops without a person in them, as scripted remediation did before it, so it is a delegated actor under the autonomy budget and an observed system under the observer principle (Chapters 4 and 17). Its report that it has converged is its own view of its own work.
First-generation AIOps
The last model in the lineage is the application of machine learning to operational data. It answered scarcity of attention to signals: the telemetry of a large estate exceeds what any team can read, and the hope was that statistical methods would find the anomaly, group the alerts and point to the cause. A later section treats what it delivered. For the lineage it is enough to say that it was layered over the other models and did not replace them.
The models side by side
| Model | Scarcity it answered | Characteristic artefact | What remained to a person |
|---|---|---|---|
| Sysadmin and runbook | Expert time at the console | Runbook, ticket queue, on-call rota | Everything: observing, deciding, acting |
| Service management | Knowledge of what changes and what depends on what | Change record, configuration database, CAB | Judgement on each significant change |
| DevOps | Flow between development and operations | Pipeline, deployment frequency, lead time | Ownership of the service in production |
| SRE | Reliability engineering skill | SLO, error budget, toil cap, blameless review | Setting objectives, spending the budget, removing toil |
| Platform engineering | Product-team attention | Internal platform, golden path | Choosing and operating the platform |
| First-generation AIOps | Attention to signals | Correlated alert group, anomaly score | Deciding on the cause and acting on it |
What each model got right
Each model contains something that the transformed operator should keep, and each has been criticised for something that its successor corrected. The criticism is part of the history, and the fair account gives both.
Service orientation
Service management made the service, not the server, the unit of operations. A service has an owner, a criticality, dependencies, an objective and a record of what happened to it. This is the substance of the service catalogues that Chapter 4 and later chapters use (SVC-NR-* and SVC-HM-*), and it is the form of management system that ISO/IEC 20000-1 asks an organisation to be able to show an auditor (48, ISO/IEC, 2018). The service view is also what the regulation of Chapter 23 assumes: the duties of DORA and NIS 2 attach to services and functions, not to machines.
Change control and its measured cost
The change advisory board is the practice on which the research is most pointed, and it deserves a careful account. The 2019 report states the positions of both sides. Proponents, supported by IT service management frameworks, claim that formal change approval leads to more stability and point out that it has been the norm for decades. Others, backed by lean and agile philosophies, argue that streamlined approval leads to faster feedback and better outcomes. The authors tested both by building two measures of how change approval was practised in respondents' organisations. They found that survey respondents were 2.6 times more likely to be low performers if their organisation required the approval of an external body, such as a CAB or a senior manager, for significant changes, and they found no evidence that a formal approval process was associated with lower change fail rates. They recommended that organisations move away from external change approval and towards peer review during development, supported by automation that detects and prevents bad changes earlier (113, Forsgren et al., 2019).
Three cautions apply to this finding. It comes from survey responses, so it reports associations between how respondents described their process and how they described their performance, and it does not establish that removing a board improves performance. The report is an industry research publication, and the book does not treat it as a controlled experiment. And the report does not conclude that nothing should review change. It recommends peer review and automation, and it gives the board a different task: since approving each individual change is impossible in a continuous delivery paradigm, the board should help teams improve their delivery process and weigh in on business decisions that require a trade-off. The book's reading is that the CAB answered a real scarcity, which was that nobody could see across the whole estate, and that the question for the transformed operator is whether the scarcity still holds. Chapter 22 returns to change authority on that basis.
Objectives, budgets, toil and learning
The SRE model supplied four ideas that this book relies on more than any other single source.
The first is that reliability is a target and not an absolute. Alvidrez wrote in the SRE book that 100 per cent is probably never the right reliability target, that the product and SRE teams jointly define a quarterly error budget based on the service's SLO, and that the budget aligns incentives and emphasises joint ownership between them (112, Beyer et al., 2016). The Workbook states the arithmetic: the error budget is 100 per cent minus the SLO. It also requires a written error budget policy that says what happens when the budget is exhausted and who takes the action, with typical actions including giving top priority to reliability bugs, focusing exclusively on reliability until the system is within its SLO, and a production freeze that halts certain changes until there is sufficient error budget to resume (243, Thurgood et al., 2018). Chapter 4 builds the autonomy budget on this pattern: a budget is a pre-agreed rule about what happens when errors are spent, written before the incident so that nobody negotiates it during one.
The second is that operational work can be measured and capped. Rau defined toil as work that is manual, repetitive, automatable, tactical and without enduring value, and that scales linearly as a service grows, and reported Google's aim to keep it below 50 per cent of each SRE's time (112, Beyer et al., 2016). Treynor Sloss described the same cap on operational work, with excess load redirected to the product development teams until it falls back within the cap. The measure matters for this book because AI removes toil unevenly. A task that is manual and repetitive is a candidate for an agent. A task that is also a place where operators keep their skills is a candidate for a deliberate exception, which Chapter 26 takes up.
The third is a standard for what deserves a page. Ewaschuk's chapter states that every page should be actionable, that a page should require human judgement, and that the four golden signals of monitoring are latency, traffic, errors and saturation (112, Beyer et al., 2016). Chapter 5 uses the signals and Chapter 6 asks which of these standards AI-assisted alerting meets.
The fourth is blameless review. Lunney and Lueder called blameless postmortems a tenet of SRE culture, focused on the contributing causes of an incident without indicting any individual or team, on the assumption that those involved had good intentions and decided on the information they had. They noted that a blame-focused culture discourages people from reporting problems, which raises the organisation's risk (112, Beyer et al., 2016). Chapter 12 builds the post-incident review on this rule, and Chapter 25 returns to it, because a review that attributes a failure to an AI-proposed action raises the same question as one that attributes it to a person.
Platforms and team design
Platform engineering contributed the observation that the form of the organisation determines what is cheap to do. A platform team that offers capabilities as a service, in the interaction mode that Team Topologies calls X-as-a-Service, lets product teams stay on the product (116, Skelton & Pais, 2025); (273, CNCF TAG App Delivery & Platforms Working Group, n.d.). The transformed operator's AI team of Chapter 16 inherits this shape: the agents are a platform capability with an owner, an interface and a service level, and not a collection of scripts that individual engineers keep.
The scarcity behind the shape
Reading the six models together suggests a pattern, which is the book's own interpretation and not a finding of any source cited above. Each practice in an operations function was designed around the fact that people's attention was the scarce resource, and each is best understood as a device for rationing it.
The ticket queue rations the order in which problems receive attention. The runbook rations expert judgement by writing it down once for many uses. The on-call rota rations the hours of the day. The CAB rations the reviewing of change by sending only the significant changes to a forum. The alert threshold rations the operator's gaze by turning a continuous signal into an occasional page. The error budget rations the argument between product and reliability by deciding in advance what counts as too much failure. The severity scale rations escalation. In each case the rationing worked, and it also had a price: the item that failed to meet the threshold, fell outside the queue's priorities or was not judged significant received less or no attention.
The pattern has a use. AI changes the price of attention in particular places. A model that can read every log line, draft a status update or summarise a ticket thread lowers the price of reading. It does not lower the price of deciding, and it does not lower the price of being accountable. The classification below separates the practices that were rationing reading, which AI loosens, from those that were rationing authority, which AI does not.
It is observable that organisations use the artefacts described above: the ISO/IEC standard is published, the SRE and DevOps literatures are public, and the platform white paper and the team design literature are in wide use. It is the book's interpretation that these are rationing devices for attention. It is expected, because it follows from the capabilities that Chapters 6 and 7 examine, that the cost of reading and summarising falls and that the practices which rationed reading will be redesigned. Whether the redesigned practices serve operators better is not established.
First-generation AIOps
The term AIOps entered the vocabulary in the second half of the 2010s. Notaro, Cardoso and Gerndt report that it was coined by Gartner in 2017, in a definition under which AIOps platforms use big data, machine learning and other advanced analytics to directly and indirectly enhance IT operations, and they note that there is no widely adopted definition. The most cited problems they found were anomaly detection, root-cause analysis, resource provisioning, failure remediation, and failure prediction and prevention (115, Notaro et al., 2021). Dang, Lin and Huang, writing from Microsoft's experience, described AIOps as empowering software and service engineers to build and operate services at scale with AI and machine learning techniques, and the same absence of an agreed definition (114, Dang et al., 2019). The absence matters to a buyer: a product labelled AIOps may do any of these things or only some of them.
What was delivered
The survey by Notaro and colleagues is the most systematic account of what the research produced. It reviewed 100 failure management solutions and divided the area into five categories by the time window of intervention. In the authors' earlier mapping study, summarised in the survey, failure detection had the most contributions (226, 33.7 per cent of those counted), followed by root-cause analysis (179, 26.7 per cent) and online failure prediction (177, 26.4 per cent). Failure prevention and remediation had the fewest, 71 and 17 contributions, and only 11 and 5 since 2018. The authors suggest a reason for the thinness of remediation: once diagnosis has established the nature of the problem, the recovery steps are often identifiable without complex models (115, Notaro et al., 2021).
Read as a description of the first generation, this gives a consistent picture. The research effort concentrated on O1 Observe and O2 Diagnose: finding the anomaly and finding the cause. The step that changes the state of the estate, O4 Restore, was left to scripted runbooks and to people. The authors also state the motivation: they describe human intervention windows that typically span several hours against the minute scale of automated systems, and argue that current operations rely heavily on manual intervention that cannot keep up with the scale of modern systems. This is their framing of the problem and not a measured result of the survey.
What was not delivered, and why
The practitioners' account is the more candid one about difficulties. Dang and colleagues listed, from their experience at Microsoft, several that recur through this book. For supervised learning there are often no clear ground-truth labels, or high-quality labels demand huge manual effort, because the data are extremely imbalanced, small in quantity or noisy. In many scenarios only unsupervised or semi-supervised models are feasible, and it is hard to have enough labels to learn what is abnormal for a service that is constantly changing. They named a risk of service interruptions caused by misbehaving machine learning models, a strong AI-solves-everything mindset that is not a realistic expectation, and engineering principles that AIOps still needed, including monitoring of data and label quality, continuous model-quality validation and the actionability of insights (114, Dang et al., 2019).
These points were made in 2019 about machine-learning models and not about the language models that Chapters 6 and 7 consider. Three of them are structural and carry over. A detector trained on history assumes that the future resembles it, which is the assumption an incident breaks. Labels for what is abnormal are scarce, so evaluation is difficult, which is why Chapter 6 asks for golden incident sets. And an AIOps component that misbehaves is itself a cause of outages, which is the seed of the thesis that the operator's AI is part of the estate it operates. Whether current systems have overcome these limits is a question for the evidence of Chapters 6 and 7, and it is not assumed here.
Lessons from other domains
Operations is not the first field in which a human supervises an automated system, and the human-factors literature on that arrangement is older than AIOps. Three works are used in this book, and the claims drawn from each are stated narrowly.
Bainbridge's paper of 1983 is the origin of the phrase ironies of automation. Its setting is industrial control, such as process plants. Its argument is that the designer who automates a task because the operator seems unreliable leaves the operator with the tasks that could not be automated, which are the monitoring of the automation and the taking over when it fails. Her ironies are that physical skills deteriorate when they are not used, so that an experienced operator can become an inexperienced one; that the takeover happens in an abnormal situation, in which the operator has had least practice; that people are poor at monitoring for rare abnormalities over long periods; that automatic control can camouflage a developing failure by compensating until it is beyond recovery; and that a reliable system therefore increases the need for training rather than reducing it. Her remedy is periodic hands-on practice, with the limit that unknown faults cannot be simulated (217, Bainbridge, 1983).
Parasuraman and Manzey reviewed the empirical studies of complacency and bias in human interaction with automation. They report that complacency arises under conditions of multiple-task load, when manual tasks compete with the automated one for the operator's attention; that it is found in both naive and expert participants and cannot be overcome with simple practice; and that automation bias leads to omission and commission errors when decision aids are imperfect, depending on attentional processes similar to those of complacency (218, Parasuraman & Manzey, 2010). AI Threat (Chapters 6 and 14) drew on the same literature for the observation that automation erodes the skills of those who must catch its errors and that automating junior work removes the route by which experts are made (299, Nordqvist, 2026).
Parasuraman, Sheridan and Wickens proposed a model in which automation applies to four classes of function, which are information acquisition, information analysis, decision and action selection, and action implementation, and in which each class can be automated across a continuum from fully manual to fully automatic. They proposed human performance consequences as the primary criterion for choosing a level (223, Parasuraman et al., 2000). The series' autonomy levels, from Level 0 Advisory to Level 4 Autonomous, set per function and action class (AI Red Team, Chapter 6), are in the same family of ideas (298, Nordqvist, 2026). That is the book's observation about a family resemblance, and it does not claim that the series' levels derive from the 2000 model.
What these works mean for operations is the book's own reading and has four parts. First, auto-remediation is the oldest widely accepted automation in operations, so the human-factors cautions about it are not new and the evidence on supervisors of automation applies to the operator of a remediation agent. Second, the self-healing mask, in which a system hides the failure by compensating for it, is Bainbridge's camouflage in a modern form, and it is the reason why Chapter 17 asks for verification by an observer that does not depend on the system being repaired. Third, an operator who has been relieved of routine recovery has less practice at the recovery that the automation cannot do, which is why the book treats competence as a claim with evidence (Chapter 26). Fourth, the literature describes what happens to attention and skill under automation; it does not describe how a team of operators behaves when the assistant is a language model, and Chapters 7 and 25 must not claim more than the studies there measured.
A ticket-era and a code-era change record
A change record is the clearest place to see the difference between the ticket era and the code era, because the same change carries a different shape in each. The two records below describe the same type of change at Hansa Mutual: a configuration change to the routing of the AI gateway of the group AI platform (SVC-HM-007). The first is the record of the change that preceded incident INC-HM-2027-0833 of 2027-09-30, as the ticket tool held it. The second is the record that the same change type would carry in the code era, held in the repository beside the configuration it changes. Chapter 8 develops the code-era record, and Chapter 9 the stages that protect it.
Worked example: a ticket-era and a code-era change record
Both records are illustrative. They show the shape of each era and are not a template for production. Identifiers CHG-HM-5870 and CHG-HM-6101 are fictional and follow the Hansa numbering of the operations profile.
The ticket-era record, in the form exported from ServiceHub:
change_id: CHG-HM-5870
type: standard
state: closed
opened: 2027-09-29
requested_by: application operations, claims
service: SVC-HM-007
summary: Update routing weights of the AI gateway
description: >
  Adjust routing weights between the hosted and the self-hosted model
  pool as agreed with the claims product owner.
risk: low
approval:
  approver: change manager, group IT
  method: pre-approved standard change template
implementation_window: 2027-09-30 10:00/10:30 Europe/Berlin
implementation_plan: Apply the configuration in all markets
backout_plan: Restore the previous weights
test_evidence: ""
cab_reviewed: false
closed_notes: Implemented as planned
The same change type in the code era, held beside the configuration:
change_id: CHG-HM-6101
service: SVC-HM-007
type: normal
authored_by: {kind: human, name: Daniel Fischer}
reviewed_by: [Ewa Kowalczyk]
diff: configs/ai-gateway/routing.yaml
policy_checks:
  - id: freeze-calendar
    result: pass
  - id: canary-required
    result: pass
rollout:
  stages: [one-market-canary, four-markets, all-markets]
  hold_minutes: 15
  stop_when: {slo: SLO-HM-007, burn_rate_above: 6}
  verifier: independent-probe
rollback:
  automatic: true
  previous: git:a41c9e2
  stop_path: platform engineer on call, outside the gateway
evidence: [probe-results, slo-burn-report]
What differs is who can read the change, what the record can prove and when the risk is tested. In the first record the approval is a property of the template: because the change type is standard, no one reviewed the content of this change, and the field for test evidence is empty. The change was then applied in all markets, and, as the baseline history records, the canary stage was skipped, so that the claims assistant failed in four markets for 47 minutes. In the second, the diff is in the record, the reviewer is named, policy checks run before the change and are recorded with a result, the rollout is staged with a stop condition tied to a service level objective, and the rollback and the stop path are stated, with the stop path held outside the system that the change affects. The second record does not remove the need for judgement. It moves judgement to the policy that defines the stages and the stop condition, and it makes that judgement inspectable.
Practical guide: classifying the practices a team has
Purpose. A team inherits practices from every model in the lineage and does not usually know which scarcity each answers. This guide gives a one-page classification that decides, per practice, whether to keep it, automate it, change its owner or retire it, before any AI is introduced into it.
Roles. The head of operations or SRE lead owns the exercise. A service owner for each service in scope contributes. The employee representatives are informed of the scope, which is practices and not people. The CISO and the privacy officer review any practice that touches personal data.
Steps.
- List the practices in use for one service, in a single register, on one line each: the queue and its priority rules, each runbook, the on-call rota, the alert rules that page, the change types and their approval routes, the incident and problem reviews. A first pass of one service takes at most half a day.
- For each, record its lineage (sysadmin, service management, DevOps, SRE, platform engineering or AIOps), the scarcity it answered, the evidence that it is used (the date of last use and the number of uses in the last quarter) and its owner.
- Mark whether the scarcity still holds. A practice that rationed reading may now be automated. A practice that rationed authority, such as who may approve a failover, stays with a named person.
- Choose a disposition: keep, automate, change owner, or retire. Retire only a practice with no use in the last year and no regulatory purpose.
- For each practice to automate, record the function (O1 to O5) and the action class, and flag it for a delegation profile (Chapter 4). Nothing is delegated at this step.
- Review the register every six months and after any major incident. Adapt the half-day and six-month defaults to the size of the estate and to what the works agreement says about reporting.
A register entry, in YAML:
- practice: out-of-hours service-desk telephony and knowledge base
  service: all services, Tier 1 first
  provider: SamDrift
  lineage: sysadmin
  scarcity_answered: expert time at night
  last_used: 2028-09-04
  uses_last_quarter: 31
  owner: Sara Ekdahl
  scarcity_still_holds: partly
  disposition: keep
  review_by: 2029-03-31
Definition of done. Every practice for the service has a lineage, a scarcity, a use record, an owner and a disposition. No entry names a person as a performance measure. The register is in version control, and the first review date is set.
Across the degrees of delegation
The history above is of operations before AI took part in it, but some delegation was already there. The table marks where existing practice sits against the series' degrees of delegation (Chapter 4), and where Mode 0 Ambient AI features already exist in service-management and monitoring products. The mapping is the book's own reading and is approximate, because a degree of delegation is set per action class in a delegation profile and most pre-AI practice has none.
| Practice already in use | Action class | Nearest degree | Mode 0 features already present | What was usually missing |
|---|---|---|---|---|
| Threshold alert that pages a person | notify | Level 0 Advisory | Anomaly scoring in monitoring products (at Hansa, the default detection in Lumenscope) | An evaluation of the false-negative rate |
| Ticket categorisation and priority suggestion | annotate | Level 0 Advisory | Classification features in the service-management tool (at Nordvik, in ServiceFlow) |
A record of who accepted or overrode the suggestion |
| Watchdog or script that restarts a failed process | restart | Close to Level 3 Bounded in shape | None required | A mandate enforced outside the script, and a stop path |
| Autoscaling within limits | scale | Close to Level 3 Bounded in shape | None assumed | A budget that counts the cost of being wrong |
| Change approved by a board | deploy, reconfigure | Level 2 Supervised, per change | None assumed | Evidence that approval changed the outcome |
| Runbook followed by a person | any | Level 1 Assisted | None assumed | An owner and a date of last test |
Nordvik Region and Hansa Mutual
The two organisations stand at different points of the lineage, and the difference sets the starting point of the book.
Nordvik Region runs an ITIL-shaped service management practice. The IT management office of ten people maintains ITIL practices, contracts and service reporting; incidents, changes, problems and the configuration database are in ServiceFlow, with an ambient classification feature (Mode 0) switched on for the service desk only. A change advisory board reviews significant changes. Out of hours, a national shared-service provider, SamDrift, answers the service desk and monitors Tier 1 services from its network operations centre, paging the Region's on-call. There is no site reliability engineering team: the platform team of seven engineers carries SRE practice, and nobody holds the title. The baseline history shows the scarcities directly. The identity provider's signing certificate expired on 2026-03-12 because no certificate inventory existed (INC-NR-2026-0071), a case of knowledge of what depends on what, which service management was meant to supply. The failed disaster-recovery test of 2027-10-12 (RST-NR-2027-002) shows that a runbook and a test that has not been repeated are not evidence of recoverability.
Hansa Mutual is further along the lineage. Its Group Site Reliability and Incident Management function of about 95 people practises SRE, with service level objectives for its Tier 1 services and a 24-hour incident commander rota; production change runs through a GitOps pipeline; and a weekly board reviews the changes that do not go through the pipeline. Its remaining ticket-era practice sits in ServiceHub and in the managed provider's night operations of the legacy policy administration platform. The incident of 2027-09-30 (INC-HM-2027-0833), in which a standard change skipped its canary stage, shows the cost of carrying a ticket-era approval route into a code-era estate: the approval was a property of the template and not of the change. It already runs an AI agent at Level 3 Bounded for restarts, certificate renewal and horizontal scaling (AIDR-0027), which is why its question in AIDR-0950 is how far autonomy may reach, while Nordvik's in AIDR-0900 is what operations becomes and what the Region can prove about recovery.
Summary
This chapter described the baseline for the book. Operations organised itself, in turn, around the system administrator and the runbook, around service management and its change control, around DevOps and the measurement of delivery, around SRE with its objectives, error budgets, toil cap and blameless review, around platform engineering, and, most recently, around the application of machine learning to operational data. Each answered something that was scarce. The book's reading is that each of the practices that remain in an estate is a device for rationing attention, and that AI lowers the price of reading while leaving the price of authority where it was.
The research gives a mixed account of the practices. The survey of delivery performance found no evidence that formal external change approval lowered change fail rates, and found that organisations with it were more likely to be low performers, while recommending peer review and automation in its place and keeping a strategic role for the board. The SRE literature supplied the objective, the budget, the toil cap and the blameless review, which later chapters reuse. First-generation AIOps concentrated on detection and diagnosis, with remediation the least studied area, and its practitioners listed label scarcity, data quality and the risk of misbehaving models among its difficulties. The human-factors work on supervising automation, from Bainbridge to Parasuraman and Manzey, predicts that the supervisors of remediation lose practice and attention, and that automatic repair can hide a failure.
The chapter concerned all five operations functions. O1 Observe and O2 Diagnose are where the first generation of AIOps concentrated. O3 Change is where the board and the pipeline offer rival answers to the same risk. O4 Restore is where scripted remediation was already close to delegation, and O5 Sustain is where toil, the error budget and the blameless review were first named. Chapter 3 turns from the past to the pressures that strain this inherited shape, and Chapter 4 defines the five functions, the autonomy budget and the observer principle that the rest of the book applies.
Sources
- ISO/IEC (2018). ISO/IEC 20000-1:2018 Information technology - Service management - Part 1: Service management system requirements. Edition 3, 14 September 2018. (48, ISO/IEC, 2018)
- Beyer, B., Jones, C., Petoff, J. & Murphy, N. R. (eds.) (2016). Site Reliability Engineering: How Google Runs Production Systems. O'Reilly Media. (112, Beyer et al., 2016)
- Beyer, B., Murphy, N. R., Rensin, D. K., Kawahara, K. & Thorne, S. (eds.) (2018). The Site Reliability Workbook: Practical Ways to Implement SRE. O'Reilly Media. (243, Thurgood et al., 2018)
- Forsgren, N., Humble, J. & Kim, G. (2018). Accelerate: The Science of Lean Software and DevOps. IT Revolution Press. (267, Forsgren et al., 2018)
- Forsgren, N., Smith, D., Humble, J. & Frazelle, J. (2019). Accelerate: State of DevOps 2019. (113, Forsgren et al., 2019)
- Dang, Y., Lin, Q. & Huang, P. (2019). AIOps: Real-World Challenges and Research Innovations. ICSE 2019 Companion. (114, Dang et al., 2019)
- Notaro, P., Cardoso, J. & Gerndt, M. (2021). A Survey of AIOps Methods for Failure Management. ACM TIST 12(6). (115, Notaro et al., 2021)
- Skelton, M. & Pais, M. (2025). Team Topologies, 2nd edition. IT Revolution Press. (116, Skelton & Pais, 2025)
- CNCF TAG App Delivery, Platforms Working Group. CNCF Platforms White Paper. (273, CNCF TAG App Delivery & Platforms Working Group, n.d.)
- Parasuraman, R., Sheridan, T. B. & Wickens, C. D. (2000). A model for types and levels of human interaction with automation. IEEE Trans. SMC-A 30(3). (223, Parasuraman et al., 2000)
- Bainbridge, L. (1983). Ironies of Automation. Automatica 19(6). (217, Bainbridge, 1983)
- Parasuraman, R. & Manzey, D. H. (2010). Complacency and Bias in Human Use of Automation: An Attentional Integration. Human Factors 52(3). (218, Parasuraman & Manzey, 2010)
- Nordqvist, G. (2025). Architecture as Code. (295, Nordqvist, 2025)
- Nordqvist, G. (2026). AI Red Team. (298, Nordqvist, 2026); AI Threat. (299, Nordqvist, 2026)
- Ansible project. Glossary. Ansible Community Documentation. (294, Ansible project, n.d.)
- Burns, B., Grant, B., Oppenheimer, D., Brewer, E. & Wilkes, J. (2016). Borg, Omega, and Kubernetes. ACM Queue 14(1), 70-93. (293, Burns et al., 2016)
- The Kubernetes Authors. Controllers. Kubernetes documentation. (153, The Kubernetes Authors, n.d.)
- Kubernetes SIG Architecture. API Conventions. (175, Kubernetes SIG Architecture, n.d.)
- OpenGitOps. GitOps Principles, version 1.0.0. (55, OpenGitOps, n.d.)
- Conway, M. E. (1968). How Do Committees Invent? Datamation, April 1968. (271, Conway, 1968)