Conclusion: Operations with AI
This chapter judges the thesis of AI Operations against the evidence of Chapters 2 to 28, states what remains open, gives the author's own projections, labelled as such, and ends with five things a reader can do on Monday. It concerns all five operations functions, O1 Observe, O2 Diagnose, O3 Change, O4 Restore and O5 Sustain, because the thesis is a claim about the loop that joins them and not about any one of them. The verdicts use the three labels of the series (AI Governance, Chapter 22) (296, Nordqvist, 2026). In this chapter "established" means observable: documented now, by a source that a reader can open. Expected means supported by a stated trend or a decided instrument. Speculation means plausible and not supported by present evidence.
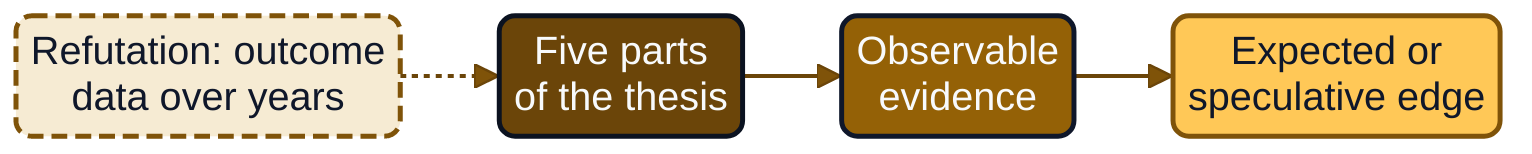
Figure 31.1: The five-part thesis with its observable core and its expected or speculative edge. The table below gives the five parts.
The table gives the five parts with the observable core and the open edge of each. Independent multi-year outcome data would refute parts 4 and 5.
| Part of the thesis | Observable core | Open edge |
|---|---|---|
| 1 Transformed, not abolished | A named person answers | Speculation: no one on call |
| 2 Autonomy matched to reversibility | Level 3 for restart and scale | Expected: widening class by class |
| 3 The operator's AI is Tier 0 | Credentials and text channels | Expected: manifests at a decision point |
| 4 The observer principle | Shared-fate failures | Speculation: a model verifier is enough |
| 5 Resilience and competence are claims | Failed restore claims | Expected: decay of manual skill |
The chapter takes over five conclusions of the earlier volumes and adds a sixth that this book supplies. AI Threat, Chapter 35, closed the series' argument: keep decisions as records that can be corrected, keep the ability to stop outside the system being stopped, keep people able to do the work and judge the output, keep dependence reversible and match autonomy to reversibility (299, Nordqvist, 2026). AI Boss, Chapter 33, added a sixth commitment, a named person in the chair for every consequence (301, Nordqvist, 2026). AI Blue, Chapter 28, put the final test of a defending team as two questions answered from records and drills: can the team show who or what decided what, and can it stop what it has started and recover (302, Nordqvist, 2026). AI Blue also labelled its projection for 2036 and named the evidence that would refute it, and AI Purple, Chapter 25, kept the future of the loop as a horizon register with thresholds (304, Nordqvist, 2026). Operations applies the same closing discipline to the function that keeps services running, and the form of each verdict below follows from it: a claim, the evidence, a label and the observation that would show the claim wrong.
How to read the verdicts
Three limits apply to every verdict, and a reader who forgets them will read the chapter as more confident than it is.
First, the evidence is of unequal strength. The public post-incident reports of Chapter 28 are primary sources and describe what happened to the organisations that wrote them. The benchmarks of Chapters 6, 7 and 10 measure agents in synthetic environments and say little about a catalogued runbook. The studies of skill, vigilance and wellbeing in Chapters 25 and 26 concern other domains, and none was found that measures operators under autonomous operations agents. The vendor announcements cited in Chapter 27 show what products exist and not what they achieve.
Second, the book's own mechanisms are designs and not findings. The eleven action classes, the default ceilings, the tolerances of the autonomy budget, the ninety-day and one-hundred-and-eighty-day clocks and the yearly legal floor under them are the book's recommendations, chosen with reasons, and Chapter 4 says that the weights are a design choice and not a measurement. A design can be well supported by the cases it answers and still lack the outcome data that would show it works.
Third, Nordvik Region and Hansa Mutual are fictional. Their records illustrate how the artefacts are used and how the numbers are read. They are not evidence for any verdict, and the verdicts rest on the sources.
The five-part thesis judged
Part 1: operations is transformed, not abolished, from the queue to the control loop
The first part of the thesis says that the work moves from handling tickets and alerts to designing, bounding and verifying closed loops, and that a named person remains the accountable conductor of the loop.
What is observable falls into three groups. Practices that put loops before queues predate AI: the SRE tradition supplied objectives, error budgets, a toil cap and blameless review (243, Thurgood et al., 2018); (253, Rau, 2017); (259, Lunney & Lueder, 2017), and the survey of delivery performance that Chapter 2 reviewed found no evidence that formal external change approval lowered change failure rates and recommended peer review and automation in its place (113, Forsgren et al., 2019). Agent products for investigation have reached general availability from at least one large provider, which shows that vendors are building toward the loop and does not show what the products achieve (291, AWS, 2026). And the instruments that apply to the two organisations place accountability on named people: the management body of a financial entity defines, approves, oversees and is responsible for the implementation of its ICT risk arrangements (DORA Article 5(2)), the management bodies of essential and important entities approve the cybersecurity risk-management measures and oversee their implementation (NIS 2 Article 20(1)), and a deployer of a high-risk AI system assigns human oversight to natural persons with the necessary competence, training and authority (AI Act Article 26(2)) (2, European Union, 2022) (3, European Union, 2022) (1, European Union, 2024).
What the evidence does not show is the size of the shift. Capability measured on software tasks has doubled about every seven months since 2019 in one study, and its authors do not present the curve as one for incident diagnosis (289, Kwa et al., 2025). On unseen faults the two benchmarks cited in Chapters 7 and 10 report that agents resolved about 11 per cent of the failures or scenarios, and a randomised trial of experienced developers found them 19 per cent slower with AI assistance while believing themselves faster (128, Xu et al., 2025) (225, Jha et al., 2025) (231, Becker et al., 2025). A transformation of the work is therefore established in direction and unproven in extent.
Verdict. That operations is organised around loops that must be bounded and verified, and that a named person answers for each Tier 1 service, is observable. That agents take a growing share of routine detection, correlation, drafting and catalogued, reversible action, class by class, is expected. That operations is abolished, or that no person is on call for a critical service, is speculation, and Chapter 27 set out why. What would show the part wrong: a supervisor's acceptance of an agent as the accountable party for a critical function, or independent incident data of the kind described under part 4. The author sees no sign of either.
Part 2: autonomy is matched to reversibility and blast radius, and has a budget
The second part says that every action class has a degree of delegation set by what can be undone, how far a mistake spreads, the agent's record and the window, that errors consume a budget, that a stop path sits outside the system it stops, and that Level 4 Autonomous is never used for four kinds of action.
The matching of delegation to reversibility is observable in practice and in the cases. Large estates have automated restarts, rollouts and cluster turnup for years, and the same account records that after a decommissioning incident the automation gained sanity checks, rate limits and idempotent workflows (252, Murphy et al., 2017). The joint guidance of the cyber security agencies of five countries asks that decisions on when human approval is needed be taken by designers and operators and not left to the agentic system (69, Five Eyes agencies, 2026). The cases of Chapter 28 are, read through the action classes, a catalogue of what each prohibition forbids. Knight Capital sent irreversible orders into a market with no halt on its own aberrant activity (80, U.S. Securities and Exchange Commission, 2013). GitLab's recovery turned on a manual delete of production data and a backup that nothing had restored from (89, GitLab, 2017). Atlassian's script, run to remove a legacy app, deleted 883 whole sites (266, Atlassian, 2022). In the AWS event of October 2025 a health-check failover rule removed nodes until engineers disabled it, an automatic class consuming its budget faster than it repaired (75, AWS, 2025). The first prohibition (irreversible action on production data) and the third (action that disables the observation or the stop path) have the strongest support, because the cases show the mechanism directly. The second (action outside a window or freeze) and the fourth (decisions about a named person's access to work) rest more on the instruments and on AI Boss than on operations incidents.
The budget is a different matter. No source in the evidence reports an organisation that counted autonomy errors, and no report of Chapter 28 describes a budget at work. The budget is the book's own proposal, borrowed from the SRE error budget and applied to delegated action, and its tolerances are a design choice. It is a sound idea to the extent that the error budget has worked in practice for service objectives, and that is a different thing from having evidence for this use.
Verdict. That autonomy is matched to reversibility and that Level 3 Bounded is defensible for restart, scale-out and certificate renewal inside a catalogued runbook, with an outcome probe, a policy decision point outside the agent and a drilled stop, is observable. That the ceilings widen class by class, to roll back and for some organisations to fail over between a defined service pair, on recorded evidence, is expected (Chapters 10 and 27). That a budget counted by an independent observer is a better trigger for lowering a level than judgement alone is the book's expected conclusion and has no outcome data behind it yet. That a fully autonomous loop could safely cover the classes the prohibitions exclude is speculation, and the book recommends against acting as if it were true. What would show the part wrong: evidence that Level 4 for an excluded class produces no more severe incidents than Level 3 with approval, or evidence that organisations holding the prohibitions have more severe incidents because of them. The first is the unlikelier, because the prohibitions follow from reversibility and not from the capability of the models.
Part 3: the operator's AI is part of the estate it operates
The third part says that remediation agents, observability pipelines, runbook libraries and configuration maps are Tier 0 assets because they hold the broadest credentials and the best map, and must be designed, contained, monitored and tested as the most privileged workloads the organisation runs.
The premise is observable and the book's reading of it is an argument from architecture. A remediation agent that can restart, deploy, scale and delete in production is in effect an administrator, and privilege risk, over-broad credentials included, is a key concern in the guidance of the cyber security agencies of five countries (69, Five Eyes agencies, 2026). Indirect prompt injection, the route by which text that outsiders can write reaches an agent's context, is documented in research (95, Greshake et al., 2023). Chapter 18 notes, however, that it knows of no published post-incident report of an operations agent steered in production by that route. The two agent cases of Chapter 28 concern evaluations of frontier systems with safeguards disabled and not enterprise operations, and a package mirror meant to restrict access became an egress path (70, UK AISI, 2026) (86, OpenAI, 2026). The inference to operations is the book's.
Verdict. That the operator's AI holds privileges that make it a high-value asset is observable. That a policy decision point outside the agent, an identity per agent, no standing credential for change or restore classes and signed runbooks become standard features of operations and agent platforms is expected, on the strength of instruments that already require access control (DORA Article 9(4)(c), NIS 2 Article 21(2)(i)) and the direction of the guidance. That agents delegating to agents can be bounded by the same manifests without new protocols is speculation. What would show the part wrong: a body of production incident data showing that agents with broad credentials and no outside decision point cause no more loss than agents with narrow, short-lived ones. The author does not expect it.
Part 4: a loop closed by machines alone can hide its own failure; the observer principle
The fourth part says that self-healing can remove the evidence of its cause, that noise reduction can suppress the alert that matters, that an agent can verify its fix with the metric it just changed, and that three tests answer this: what verifies is independent of what performed, the observer does not depend on the system observed, and the stop path works when the platform does not.
This is the best supported part of the thesis in the evidence of failure. In the eleven cases of Chapter 28 the observer, the verifier or the notification path failed together with the thing it served, or was misled by it, in most of them: the validator and the code shared an assumption about 21 inputs where the code supplied 20 (78, CrowdStrike, 2024); the audit tool failed on its own account and the engineers' tools and access ran on the network the command had removed (79, Janardhan, 2021); customers' monitoring hosted on the failing cloud fell silent with it (76, Google Cloud, 2025); and a coincidence between a healthy-failing alternation and an unavailable independent status page was first read as an attack (77, Prince, 2025). GitLab's backup failure was reported by email that the receiving server rejected, so that silence read as health (89, GitLab, 2017). The pattern is a pattern across cases chosen for the book, and a selection of reported failures cannot show how often independent observers work, because the successes are not reported.
The evidence on models bears on the cheap remedy. Capable models from different providers make highly correlated errors, and language-model evaluators recognise and favour their own generations (103, Kim et al., 2025) (104, Panickssery et al., 2024). A second model of the same capability is therefore a partial remedy for a shared blind spot, and the book's layered answer (scripts and synthetic transactions where possible, a separate credential and failure domain, a heartbeat that alarms on silence, seeded faults with a catch rate and reproduction by a person) rests on that. The conclusion is the book's. Whether a given organisation's observers hold is shown only by its own seeded faults.
Verdict. That observers share the fate of what they observe, and that the verifier of a repair can share its assumptions, is observable. That a verifier independent in model, data, authorship, vendor and time is more reliable than one that shares them, for outcome claims, is expected to hold while the correlation among capable models persists. That a model-based verifier alone is sufficient for the irreversible classes is speculation. What would show the part wrong: the refutation stated in the disposition of this book. Independent incident data over several years that showed fully autonomous remediation, with no independent verification and no practised manual operation, yielding fewer customer-impacting incidents and a lighter tail of severe events than a loop that keeps those properties, would show the safeguards to be a cost that can be dropped. The author knows of no such data and does not expect it soon, because the organisations that run such loops do not, as far as the author has found, publish the data that would test the claim.
Part 5: resilience is a claim that needs evidence, and so is the operator's competence
The fifth part says that "recoverable" is a statement with a scope, an objective, a measurement, a date and a result, that untested is not recoverable and evidence expires, and that manual skill decays unless practised on purpose.
The first half is observable in the cases and in the law. GitLab's backups were asserted and nothing had restored from the logical one (89, GitLab, 2017). Atlassian's restore met the recovery point objective and missed the recovery time objective because no tooling restored many sites at once, so a claim true for one customer was untested for hundreds (266, Atlassian, 2022). DORA Article 24(6) requires, at least yearly, appropriate tests on all ICT systems and applications supporting critical or important functions for financial entities other than microenterprises, and NIS 2 Article 21(2)(c) names business continuity, backup management and disaster recovery among the measures (2, European Union, 2022) (3, European Union, 2022). The register of Chapter 19, with its derived statuses and its expiry by clock and by condition, is the book's design for turning those demands into evidence, and no source tests the design.
The second half is the weakest in direct evidence. Bainbridge's analysis and the review of complacency and automation bias give the mechanism, and the studies cited in Chapter 26 show that unaided performance can fall after use of an aid: in a multicentre observational study of colonoscopy, in school mathematics, and in a preprint on programming (217, Bainbridge, 1983) (218, Parasuraman & Manzey, 2010) (234, Budzyń et al., 2025) (235, Bastani et al., 2025) (236, Shen & Tamkin, 2026). The studies differ in design, one is observational, one is not peer reviewed, and none concerns operators.
Verdict. That recoverability claims fail at dimensions they never named, and that evidence ages, is observable. That continuous recovery verification, with tests triggered by change and a register that recomputes statuses, becomes common is expected. That unaided performance of the cognitive part of recovery decays in operators who stop practising is expected by analogy and has not been measured in operators. That wholesale loss of the craft, or that AI certifies recoverability to a supervisor without a person's attestation, is speculation. What would show the part wrong: over four consecutive quarters of an organisation's own game days, teams that had not practised manual recovery for twelve months meeting the restore objective as often as teams that had, or a series of restore tests in which the register's status disagreed with the test result in the direction of the declared claim. Chapter 27 gave the same first threshold.
The five verdicts together
The parts are not equally strong. Part 4 and the first half of part 5 rest on documented failures. Part 1 rests on instruments and on practice, and part 3 on architecture and guidance, with limited incident data. Part 2 is well supported in its matching rule and unsupported in its budget. The competence half of part 5 is expected and unmeasured in operators. A reader who must choose which parts to rely on first should rely on the observer principle and the evidence claim, and treat the budget as a hypothesis that the organisation's own records will test.
The observer principle
The observer principle is the book's central rule and its most transferable contribution. It is the operations form of the independence principle of AI Purple, Chapter 15 (304, Nordqvist, 2026), and it answers one question about every action an agent performs: what verifies it, and what do the verifier and the action share. If the answer cannot be given, the action is not delegated.
Three properties make the rule usable. It is graded by action class, so the cost of independence falls where reversibility is least: a read needs a record, a restart needs an outcome probe, and a rollback, a failover and a restore over existing data need the strongest independence and a stop path drilled within its target (Chapter 17). It is testable, because an observer that has never caught a seeded fault is a declaration and not a control, and the catch rate is a number that can be reported to a board. And it is cheap where it matters most. The most valuable observers in the record were not elaborate: a scripted transaction from another network, a heartbeat that alarms on silence, a read-only identity, a delay before success is declared. They use no model and fail loudly.
The rule also marks the book's limits. It does not make a loop safe, and an independent observer can be wrong, can cost sleep when it pages at night and can itself become a Tier 0 asset. The rule bounds a loop's failure to the evidence about it. That is a smaller claim than safety and a more useful one.
Open questions
The book leaves seven questions open, and each is one that an organisation can help to answer by recording the right data.
- How much manual practice is the minimum? The concerned ask for a floor and the calm ask for evidence that it is needed. The interval of ninety days for a manual run with the agent off and the rule of two evidenced holders per window are the book's defaults, and the only way to learn whether they are too much or too little is to compare drill results with unplanned incident performance over years.
- How much does a second model of a different family buy? The research reports correlated errors among capable models and self-preference in evaluators, and does not give a figure for operations verification. The seeded-fault catch rate of an organisation's own observer is the measure.
- Does AI relieve or intensify the load of on-call? Chapter 25 found no independent study of operators' wellbeing under autonomous operations agents. The on-call charter decides it team by team, and the data it collects, reported for rotas and never for named engineers, is the first evidence.
- Where does the next generation of operators come from? If entry tasks are automated, the route into the craft must be designed (Chapter 26). Whether designed first rungs, attempt-first rules and rotation produce operators who can recover a service by hand is untested.
- What do providers' own agents do inside the estate? Provider AI that acts under rules a customer cannot see is observable in the baseline records of both organisations, and a contract right to inject a test is a promise until the first test shows it works (Chapters 21 and 24).
- How should reporting clocks apply when an agent's action causes an incident? The clocks of NIS 2 Article 23, DORA Articles 17 to 19, AI Act Article 73 and GDPR Article 33 overlap, and Chapter 14 gave a clock sheet. The classification of an agent-caused incident has few precedents and the supervisors' practice is still forming.
- Is the autonomy budget a good trigger or a target to be gamed? Chapter 20 warned of both. Budget consumption is valid only when the verifying probe is independent of the acting agent, and a budget never touched in a year is a signal that a class sees little use or that the observer is not counting.
The author's projections
This section is the author's judgement. It goes beyond the evidence of the preceding chapters, it is the part of the book most likely to be wrong, and it is written to be falsified. Chapter 27 gave the projections about the person on call in 2036 and the five thresholds that would change them, and this chapter does not repeat them. The projections below concern how the practice of this book may develop in the next five years, and each carries one of the three labels and is marked as the author's judgement.
- Expected (author's judgement): within five years supervisors of financial entities will ask for recovery evidence in the form of a register, each claim with a scope, a test date and a result, and will treat an untested claim as untested. The basis is the yearly testing duty of DORA Article 24(6), the requirement of Chapter 19 that results be documented, and the cost of a register to an entity that already keeps a register of information. I hold this with more confidence than the other four.
- Expected (author's judgement): the first published post-incident reports that name an operations agent as a contributing cause will describe a credential or a change path and not a faulty diagnosis. The basis is that the cases of Chapter 28 already describe automation as the means by which a small trigger reached its extent, and the agent's credential is the new route to the same pattern.
- Speculation (author's judgement): providers of managed operations will offer agents that act at Level 3 across many clients before customers have a contractual way to test them, and the contest of the next five years will be over the right to inject a test and to read the record. If I am wrong, it is more likely that the right to test is conceded early because supervisors of financial entities require it of critical providers.
- Speculation (author's judgement): the dashboard of an operations function in 2033 will show evidence age beside every green figure, and organisations that adopted this early will find that their first honest numbers were lower than their first dashboards, as the illustrative first year of AI Purple found for coverage (304, Nordqvist, 2026). If I am wrong, it will be because the figure was reported and then ignored.
- Speculation (author's judgement): the early-career route into operations will be the thing organisations get most wrong, because the cost of a missing operator appears years after the decision that caused it. I would advise organisations to treat the first rungs as a product with an owner. If I am wrong, it is more likely that agents themselves will provide enough supervised practice that novices gain, which the study of skill formation cited in Chapter 26 suggests is possible under some conditions (236, Shen & Tamkin, 2026).
What would change these views is recorded in the same way as in Chapter 27. If supervisors' tests of the next five years ask only for plans and policies, projection 1 is wrong. If the first public reports of agent-caused incidents describe wrong diagnoses and not credentials or change paths, projection 2 is wrong. If providers concede a testing right in their standard terms, the contest of projection 3 does not occur.
What to do on Monday
The five actions below take one person a few hours each. Each answers one part of the thesis, and each can be done with the records an organisation already has and no AI at all. Their order is the order of the thesis.
Practical guide: five things on Monday and the first week
Purpose. Turn the verdicts into a first week of work that produces five written records and a list of gaps, so that the organisation can see what it can prove.
Roles. The head of operations or the SRE lead does the work. The service owner, an incident commander, the CISO and the head of operational resilience, where one exists, are consulted. Employee representatives see the charter before it is adopted if it touches rotas, roles or the monitoring of staff.
Steps.
- Write the loop for one Tier 1 service on one page (part 1). Name the service owner, the objective, the five functions as they apply to the service, who answers at each, and who may declare an incident. Use the charter in the worked example below. Done when a person who was not in the room can say who answers for the service at three in the morning.
- Set the ceiling for each action class and name who can stop (part 2). List the action classes that any agent, pipeline or provider can perform on the service. Give each a ceiling, with Level 4 Autonomous excluded for the four prohibited kinds, treating every unlisted class as undelegated. Name the people who can stop an agent without approval and the route that does not pass through the agent's platform. Done when every technical permission an agent holds is matched by a ceiling or is removed.
- List the identities that can change production (part 3). For each, record whether it is a person, a pipeline or an agent, whether its credential is standing or issued for the action, and who owns it. Mark the shared and the standing ones. Done when the list exists, each entry has an owner, and the shared and standing credentials that an agent could inherit are on a removal list with a date.
- Pick one automatic repair and ask what verifies it (part 4). Take the last automated fix that closed an incident. Name the verifier, its author, its data, its identity and its failure domain, and say whether any of them is shared with the action. If a shared dimension cannot be removed this quarter, hold the class at Level 2 Supervised. Done when the answer is written and the class has a ceiling that agrees with it.
- Find the oldest "recoverable" claim and write its six parts (part 5). Take the most recent statement that a Tier 1 service is recoverable. Write its subject, scenario, objective, measured result, date and expiry. If one is missing, record the claim as untested and schedule the test. Choose one runbook that an agent runs and schedule a manual run by an evidenced person who did not write it, with the agent off, for the coming quarter. Done when the register has a date against the claim and the drill is in the diary.
Through the rest of the week. Review the five records with the service owner and the head of operational resilience, put them in version control, and record the decision in an AI Decision Record with a review date. Set a recurring review at 90 days for the ceilings and the drill, and at 180 days for the register. Report the result for the service or the team and never for a named engineer, and do so only after agreeing the measures with employee representatives where an agreement applies.
Definition of done. The five records exist in version control, each with an owner and a date; at least one gap is on the list with a named person and a date; the approver is not the author; and the next review is in the diary.
Worked example: operations charter CHR-NR-OPS-01
Nordvik Region's service SVC-NR-002, the citizen e-service portal, is a Tier 1 service with an objective of 99.9 per cent per month, a recovery time objective of 2 hours and a recovery point objective of 5 minutes. The charter below is illustrative and fictional. It is dated 2028-11-20, the day on which OBS-NR-0001 came into force, and it states plainly what the Region could show on that day: a failed failover test with no re-test, an observer that had not yet caught a seeded fault, and ceilings set below what an agent could technically do.
charter: CHR-NR-OPS-01          # illustrative
service: SVC-NR-002
as_of: 2028-11-20
decision_record: AIDR-0900
accountable: "Henrik Dahl, Head of IT and Digitalisation"
service_owner: "unit head, owner of SVC-NR-002"
objective: {record: SLO-NR-002, availability: 99.9, period: month}
recovery: {rto_hours: 2, rpo_minutes: 5}
loop:
  O1: {owner: "platform lead", observer: OBS-NR-0001}
  O2: {incident_commander: "duty manager rota of four", assistant: "NR-OPS-001 at Level 0 Advisory"}
  O3: {approver: "change authority per DRF-NR-001", first_ring: required}
  O4: {runbooks: "owned by the senior platform engineer", stop: "see stop"}
  O5: {problem_owner: "IT management office", review_days: 90}
delegation:                      # highest level per action class; unlisted = undelegated
  read: {level: 4, within: "data class internal"}
  annotate: {level: 4}
  scale_out: {level: 2}
  restart_stateless: {level: 2}
  certificate_renewal: {level: 2}
  roll_back: {level: 2}
  fail_over: {level: 1}
  delete_production_data: {level: not_delegated}
  restore_overwrite: {level: 1, executor: "named person"}
  disable_alert_probe_or_stop: {level: not_delegated}
  level_4_never: [irreversible_production_data, outside_window_or_freeze_critical, disables_observation_or_stop, decides_named_person_access]
claims:
  - {id: "SVC-NR-002/failover-to-recovery-site", status: failed, test: RST-NR-2027-002, date: 2027-10-12, measured_hours: 5.33, objective_hours: 2, retest: none}
  - {id: "SVC-NR-002/observer-catches-seeded-fault", status: untested, first_seed: "2029-Q1"}
stop: {holders: ["duty manager on call", "platform lead"], approval: none, path: "outside the Region Cloud control plane", last_drill: 2028-11-07}
manual_practice: {interval_days: 90, agent_off: true, holder: "evidenced person who did not write the runbook"}
review: {every_days: 90, next: 2029-02-18}
The charter says what is true and no more. The failover claim is failed, as RST-NR-2027-002 measured 5 hours 20 minutes against 2 hours, and it stays failed until a later test passes. The observer claim is untested because the first seeded fault is planned for the first quarter of 2029 (AIDR-0910). The stop was drilled once, on 2028-11-07, and the field records that date; one drill is the start of a quarterly series and not yet a record of a stop that has held, so the Region would not describe the stop as proven. The ceilings are below the defaults of Chapter 10 for a Level 3 class because OBS-NR-0001 has not yet shown that it catches faults.
Across the degrees of delegation
The table states the ceilings that the author recommends as the starting point for an organisation that has the observer, the stop path and the policy decision point of Chapters 16 and 17, and the condition under which each holds. They are defaults to be set in a delegation profile on an organisation's own evidence and are the book's recommendation, not a requirement of any instrument. The instruments of Chapter 23 do not set levels of autonomy for operations, with the exceptions of Article 14 of the AI Act and Article 22 of the GDPR.
| Action class | Recommended ceiling | Condition for holding it |
|---|---|---|
| read, annotate | Level 4 Autonomous, within data class | Marked as agent-authored; redaction where the data class requires it |
| notify | Level 3 Bounded internal; Level 1 Assisted external | Routing fixed by the service record; a person sends messages to customers or supervisors |
| scale out | Level 3 Bounded | Quota, cost cap and an outcome probe in a separate failure domain |
| restart (stateless) | Level 3 Bounded | Catalogued runbook, rate limit with back-off, independent probe, drilled stop |
| certificate renewal | Level 3 Bounded | Inventory of expiry dates; authority named in the profile |
| reconfigure an alert, threshold or monitor | Level 0 Advisory | A person makes the change through O3; never Level 4 |
| deploy | Level 2 Supervised; Level 3 for a pre-approved standard change | First ring for every change that alters runtime behaviour; verifier that is not the releaser |
| roll back | Level 2 Supervised; Level 3 expected on evidence | Observer catch rate and stop drill inside target for the class (Chapter 17) |
| fail over | Level 1 to Level 2; Level 3 for a defined service pair is expected on evidence | A verified claim, supervised failovers, a drilled stop; the incident commander decides |
| delete production data | Not delegated | Level 4 prohibition: irreversible action on production data |
| restore over existing data | Level 1 Assisted | A named person executes after a restore into a separate target has been compared |
| disable an observer, alert or the stop path | Not delegated | Level 4 prohibition |
Authority, the stop, the closure of an action in the problem register and the acceptance of risk are not delegated at any level. The table is a ceiling and not an entitlement: a class falls to Level 2 when its budget is spent, when something it relies on changes or when its evidence expires.
Nordvik Region and Hansa Mutual
Both organisations received a version of the same question in September 2028, and both can now answer it in the book's terms. Nordvik's regional executive committee asked what operations becomes and what the Region can prove about recovery (AIDR-0900), and Hansa Mutual's risk committee asked how far the autonomy of the IT-operations agent may reach (AIDR-0950). Both first reports are due on 2029-03-31. The two-year plans that carry the answers into action are those of Chapter 30; what follows is the conclusion that the evidence supports.
Nordvik Region can prove little about recovery and can say exactly how little. It holds one passing restore test, RST-NR-2027-001 of 2027-04-20 (3 hours 5 minutes against 4 hours), whose 180-day clock ended on 2027-10-17, and one failed failover test with no re-test, RST-NR-2027-002 of 2027-10-12 (5 hours 20 minutes against 2 hours). The conclusion is that it may not write "recoverable" for either claim at the start of the programme, and the first work is the re-test and the observer. It has no Mode 5 agent, and its operations assistant NR-OPS-001 is at Level 0 Advisory. AIDR-0910 (2028-11-06) holds that no scripted runbook reaches Level 3 Bounded until OBS-NR-0001 is in force, effective 2028-11-20, with the first seeded fault in the first quarter of 2029. Its dependencies on SamDrift for DNS, identity federation and the recovery site mean that its leverage lies in the contract and the few runbooks it owns, and that the question for 2029 is whether to begin the delegation of any class at all. The agreement MBL-NR-IT-2027-01 applies to every measure above.
Hansa Mutual can prove more and has more to lose. Its IT-operations agent HM-OPS-001 operates at Level 3 Bounded for restart, certificate renewal and horizontal scaling and at Level 2 for configuration change and rollback, and AIDR-0960 (2028-11-06) keeps restart at Level 3 on condition of OBS-HM-0001. The game day of 2028-10-24 found that the remediation agent and its verification step shared a model family, an identity and a signal, and its first stop drill took 17 minutes against a target of 5 (STOP-HM-ITOPS-2027-Q1-01). Its claims core restore test failed on time (RST-HM-2027-004, 5 hours 40 minutes against 4 hours), and its payments failover passed (RST-HM-2027-007, 1 hour 35 minutes against 2 hours on 2027-10-05) but has stood expired since 2028-04-02 on the 180-day clock. The conclusion for the board's question follows the rule of Chapters 10 and 17: no level rises without a verified claim behind the recovery the class performs, a seeded-fault result within target and a stop drill inside its target, and the extension to rollback and failover waits for them. DORA applies, so Articles 5, 11 and 24 make this a matter for the management body and for a supervisor who may ask. The operations annex KBV-IT-2024-OPS governs rotas and the measures about engineers.
The organisations differ in what the conclusion asks of them. Nordvik has to build an observer where it had none and prove a recovery it has only failed, and Hansa has to separate roles that its own agent had merged and decide how far to go. For both, the first honest numbers are lower than the first dashboards.
Summary
This chapter judged the five-part thesis of AI Operations and concerns all five operations functions: O1 Observe, O2 Diagnose, O3 Change, O4 Restore and O5 Sustain. The verdicts are that operations is transformed in direction and that a named person answers for each Tier 1 service (observable), with the widening of delegation expected and the abolition of the role speculative; that autonomy matched to reversibility is observable in practice and in the cases, while the autonomy budget is the book's own proposal without outcome data; that the operator's AI is a Tier 0 asset, observable as a premise and expected to be governed by a policy point outside the agent; that a loop closed by machines alone hides its own failure, which the public reports show in most of the cases examined; and that resilience and competence are claims with an age, observable for recovery and expected, though unmeasured in operators, for skill.
The observer principle is the rule that carries the thesis: what verifies an action is independent of what performed it, the observer does not depend on the system observed, and the stop path works when the platform does not. The thesis would be shown wrong by independent incident data over several years in which autonomous remediation without independent verification and without practised manual operation did better than a loop that keeps both, or by operators who do not practise manual recovery handling novel failures as well as those who do. The author knows of neither and has recorded the thresholds so that organisations can look for them in their own data.
The five things to do on Monday are to write the loop of one Tier 1 service on one page, to set the ceiling for each action class and name who can stop, to list the identities that can change production, to ask what verifies the last automatic repair and whether it shares anything with it, and to write the six parts of the oldest recoverable claim and schedule a manual drill with the agent off. Each can be done with the records an organisation already has. The book ends here, and what remains is the register that each organisation keeps of its own claims, tests and results.
Sources
- European Parliament and Council of the European Union. Regulation (EU) 2024/1689 laying down harmonised rules on artificial intelligence (Artificial Intelligence Act). (1, European Union, 2024)
- European Parliament and Council of the European Union. Regulation (EU) 2022/2554 on digital operational resilience for the financial sector (DORA). (2, European Union, 2022)
- European Parliament and Council of the European Union. Directive (EU) 2022/2555 on measures for a high common level of cybersecurity across the Union (NIS 2 Directive). (3, European Union, 2022)
- Five Eyes cyber security agencies. Careful adoption of agentic AI services. Joint guidance, 2026. (69, Five Eyes agencies, 2026)
- AI Security Institute. Incident Report: unsanctioned agent behaviour during cyber testing. 2026. (70, UK AISI, 2026)
- OpenAI. OpenAI – Hugging Face Incident Technical Report. 2026. (86, OpenAI, 2026)
- Nordqvist, G. AI Governance. (296, Nordqvist, 2026)
- Nordqvist, G. AI Threat. (299, Nordqvist, 2026)
- Nordqvist, G. AI Boss. (301, Nordqvist, 2026)
- Nordqvist, G. AI Blue. (302, Nordqvist, 2026)
- Nordqvist, G. AI Purple. (304, Nordqvist, 2026)
- Bainbridge, L. Ironies of Automation. (217, Bainbridge, 1983)
- Parasuraman, R. and Manzey, D. H. Complacency and Bias in Human Use of Automation. (218, Parasuraman & Manzey, 2010)
- Murphy, N. R., Looney, J. and Kacirek, M. The Evolution of Automation at Google. (252, Murphy et al., 2017)
- GitLab. Postmortem of database outage of January 31. (89, GitLab, 2017)
- Atlassian. Post-Incident Review on the Atlassian April 2022 outage. (266, Atlassian, 2022)
- CrowdStrike. External Technical Root Cause Analysis: Channel File 291. (78, CrowdStrike, 2024)
- Janardhan, S. More details about the October 4 outage. (79, Janardhan, 2021)
- Google Cloud. Incident Report, 12 June 2025. (76, Google Cloud, 2025)
- Prince, M. Cloudflare outage on November 18, 2025. (77, Prince, 2025)
- U.S. Securities and Exchange Commission. In the Matter of Knight Capital Americas LLC. (80, U.S. Securities and Exchange Commission, 2013)
- Amazon Web Services. Summary of the Amazon DynamoDB Service Disruption in the Northern Virginia (US-EAST-1) Region. (75, AWS, 2025)
- Xu, J. et al. OpenRCA. (128, Xu et al., 2025)
- Jha, S. et al. ITBench. (225, Jha et al., 2025)
- Becker, J. et al. Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity. (231, Becker et al., 2025)
- Kwa, T. et al. Measuring AI Ability to Complete Long Tasks. (289, Kwa et al., 2025)
- Amazon Web Services. AWS DevOps Agent is now generally available. (291, AWS, 2026)
- Kim, E. et al. Correlated Errors in Large Language Models. (103, Kim et al., 2025)
- Panickssery, A., Bowman, S. R. and Feng, S. LLM Evaluators Recognize and Favor Their Own Generations. (104, Panickssery et al., 2024)
- Greshake, K. et al. Not what you've signed up for: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection. (95, Greshake et al., 2023)
- Budzyń, K. et al. Endoscopist deskilling risk after exposure to artificial intelligence in colonoscopy. (234, Budzyń et al., 2025)
- Bastani, H. et al. Generative AI without guardrails can harm learning. (235, Bastani et al., 2025)
- Shen, J. H. and Tamkin, A. How AI Impacts Skill Formation. (236, Shen & Tamkin, 2026)
- Forsgren, N. et al. Accelerate: State of DevOps 2019. (113, Forsgren et al., 2019)