Observe: Telemetry, Observability and Service Level Objectives
Every other function of the operations loop depends on this one. An operator cannot diagnose what has not been seen, cannot change a service safely without knowing its state before and after, and cannot restore a service without knowing when it is restored. This chapter concerns O1 Observe: the telemetry that a service emits, the service level objectives that say what good looks like for its users, the alerts that call a person when the objective is at risk, the map that says who owns what, and the cost and legal limits on seeing. It treats the function without AI first. Chapter 6 then changes it, and takes up O2 Diagnose as it does so, because correlation, anomaly detection and language-model summaries act on the signals, indicators and objectives described here, and an organisation that has none of these cannot say whether an AI feature has made its observation better or worse.
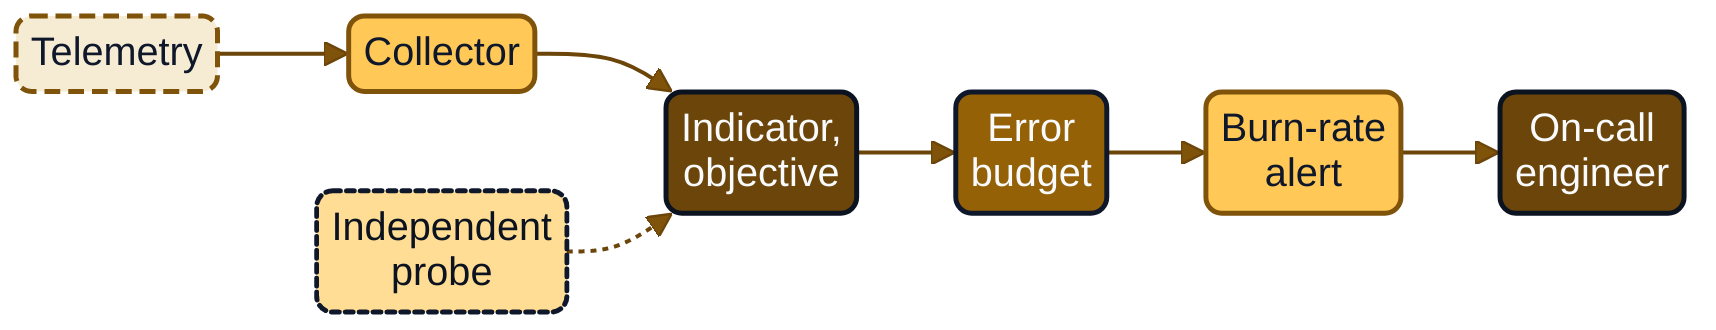
Figure 5.1: From signals to objectives: telemetry becomes an indicator, an objective, an error budget and a burn-rate alert, with an independent probe outside the platform.
The chapter builds on conclusions of the earlier volumes. Evidence is machine-collected, versioned and dated (F4 and F20; Architecture as Code (Chapter 15A) and AI Governance, Chapter 11) (295, Nordqvist, 2025); (296, Nordqvist, 2026). A detection is a record with an owner and a test, and it counts only when a recent test shows that it fires (F95; AI Blue, Chapters 6 and 11). Coverage and, in this book, resilience are claims with a date and an expiry (F119; AI Purple, Chapter 17). Observation is comparison with a written expectation, with the ground truth held outside the system observed (F125; AI Purple, Chapter 9). AI Platform and Security, Chapter 21, treated observability and drift for the AI platform (297, Nordqvist, 2026); this chapter takes the general case, for every service the operator runs.
What observing is for
Observing serves one purpose: to know whether a service is good for the people who use it, early enough to act. A large share of the monitoring that organisations inherited was built to answer a different question, whether the machines are busy, and its natural outputs are utilisation graphs and threshold alerts on processor load, free disk and queue depth. Such signals are useful in diagnosis. As the main source of pages they have a known weakness: a machine can be at ninety per cent of its processor capacity while every user is served well, and a service can fail every request while every machine reports healthy.
The Google SRE book states the distinction as the difference between a symptom and a cause. Monitoring should answer what is broken and why, and the chapter on monitoring calls the separation one of the most important in writing monitoring with high signal and low noise (242, Ewaschuk, 2017). A symptom is what a user or a calling system experiences, for example that requests fail; a cause is an intermediate condition that may or may not produce a symptom, for example that a database refuses connections. The same chapter argues that every page should be actionable and urgent, that a page needing only a robotic response should not be a page, and that paging effort should go mostly into symptoms (242, Ewaschuk, 2017). They are principles from one organisation's practice, a well-argued starting point and not a measured result.
Three consequences shape the rest of the chapter. First, the unit of observation is the service as a user journey, not the host. Second, the observer is itself a service with its own failure modes, and an operations function that cannot say when it is blind has not observed anything; Chapter 17 treats this as the observer principle, and this chapter records its first form, that the observation pipeline carries its own objective and an independent probe. Third, seeing costs money, attention and, where telemetry contains personal data, legal exposure, so that what is collected, for how long and by whom it may be read are design decisions with an owner.
Observing is a function with its own evidence
The thesis of the book states that resilience and competence are claims that need evidence, and the same holds for observation. "We would see it" is a claim about an alert, a probe, a parser and a person, true on a date and only until something changes. At Nordvik Region, on 2026-03-12 the signing certificate of the identity provider expired at 06:40 and staff could not sign in for 95 minutes (INC-NR-2026-0071, SVC-NR-004, Tier 1). No certificate inventory existed, so no signal anticipated the expiry, and the review recorded certificate expiry monitoring as its action: the expiry date is a measured quantity that needs an owner.
Signals
A service reports on itself through several kinds of signal, which differ in cost, in precision and in what they can answer. The OpenTelemetry project, the open standard for instrumentation and collection, defines traces, which track the path of a request through an application, metrics, which capture a measurement at runtime, and logs, which record an event, with baggage carrying contextual information between signals (49, OpenTelemetry, n.d.). Events, a specific type of log, and profiles, which record resource use at code level, were under development or at proposal stage at the access date (49, OpenTelemetry, n.d.). This book uses "events" in the operator's sense for state changes that are not requests, such as a deployment, a configuration push, a scaling action or a certificate renewal.
Metrics are numbers over time: cheap to store, easy to aggregate and the natural input for objectives and alerts, but unable to answer questions not anticipated when the metric was defined. Logs carry detail and therefore cost and risk: volume, retention and personal data. Traces follow one request across services and show where time went and which dependency failed, which makes a service map observed and not declared. Events place changes on the same timeline as the symptoms, the basis for the question "what changed" that Chapter 7 puts to the incident assistant.
The SRE book gives a compact checklist for a user-facing system, the four golden signals: latency, traffic, errors and saturation (242, Ewaschuk, 2017). It adds two points that practice often lacks. Latency of successful and of failed requests should be tracked separately, since a fast error can flatter an average; and errors include requests that fail implicitly, such as a success response with the wrong content, and by policy, such as a response that exceeds a committed time limit (242, Ewaschuk, 2017).
One instrumentation standard
OpenTelemetry matters to the operator for an architectural reason: it separates the instrumentation of a service from the choice of the system that stores and analyses the telemetry. A service instrumented to the standard can send its signals through a collector, a pipeline component that receives, processes and exports telemetry, to one back end today and to another after a contract ends, and exit from an observability vendor is an operational and regulatory concern (Chapter 24). Convergence on this standard is observable: both organisations of this book collect through OpenTelemetry collectors, Nordvik Region into an open-source stack on the Region Cloud and Hansa Mutual into the SaaS observability vendor Lumenscope. Dashboards, alert rules and objectives, however, are written in the query language of a back end and are not portable by the standard alone.
Signals from outside the platform
Some of the most valuable signals come from outside the estate. A synthetic probe is a scripted request that exercises a user journey at a fixed interval from a place the operator chooses. It produces steady traffic on a service that is quiet at night, measures what a user sees, and, run from outside the platform, keeps working when the platform's own telemetry fails. A provider's status page is a signal of another kind: evidence of what the provider reports about its own service. Nordvik Region's baseline incident INC-NR-2027-0298 shows both. A SamDrift DNS fault made the e-services unreachable from outside for 70 minutes (SVC-NR-002, SVC-NR-004) and the Region's own monitoring saw it 22 minutes after SamDrift's status page. A probe from outside the Region's network, and ingestion of the provider's status as an event, would have closed most of that gap. This is the book's own reasoning and was not tested in the incident.
The converse failure belongs to Hansa Mutual's baseline. On 2027-05-20 the ingestion of Lumenscope failed for 3 hours 10 minutes, and the group was blind for that period on 14 services, with the status page as the only signal (INC-HM-2027-0572). The observer was a dependency of what it observed. Chapter 17 designs against this; the minimum at this stage is that every collector emits a heartbeat, that something other than the observability vendor receives it, and that the pipeline's freshness has an objective of its own, in the same form as the objectives of the services it serves.
Indicators, objectives and error budgets
A signal becomes a basis for a decision when it is turned into an indicator and an objective. The vocabulary comes from site reliability engineering and is used here as the SRE book defines it. A service level indicator (SLI) is a carefully defined quantitative measure of some aspect of the service provided, such as latency, error rate, throughput or availability. A service level objective (SLO) is a target value or range for a service level measured by an indicator. A service level agreement (SLA) is a contract with users that includes consequences for meeting or missing the objectives it contains (241, Jones et al., 2017). The SRE book offers a test for telling the last two apart: ask what happens if the objective is missed, and if there is no explicit consequence, it is probably an objective (241, Jones et al., 2017). Nordvik Region's objectives are its own targets with no contractual penalty; the risk tolerance for ICT risk of Hansa Mutual is determined by its management body (DORA Article 5(2)(d)) and the framework analyses the impact tolerance for ICT disruptions (DORA Article 6(8)(b)) (2, European Union, 2022), within which the impact tolerances of its critical or important functions are set, as the operations profile records. The recovery time objective (RTO) and recovery point objective (RPO) are a different kind of target again. An SLO describes the service while it runs, an RTO and an RPO describe what is promised after a failure, and Chapter 19 treats the evidence for the latter.
From a user journey to an indicator
The SRE Workbook starts the work from the critical user journey, a sequence of tasks central to the experience of a user, such as searching for a product, adding it to a cart and completing a purchase (243, Thurgood et al., 2018). Such journeys rarely map onto an existing metric, because several steps can fail at any point. It also separates the specification of an indicator, the outcome that matters to users independent of how it is measured, from the implementation, the specification plus a way of measuring it. Each implementation has trade-offs of quality, coverage and cost: server logs miss requests that never reach the backend, probes catch network failures but may miss problems that affect some users only, and in-page instrumentation best reflects the experience but needs code changes (243, Thurgood et al., 2018).
The distinction explains a baseline incident. On 2026-09-22 a TriageSoft release changed a queue setting and the ranking of benefit claims stalled for 5 hours 10 minutes (INC-NR-2026-0214, SVC-NR-001); caseworkers fell back to date order. An availability probe on the service would have shown a service that was up. The Region's objective for SVC-NR-001, that a claim is ranked within 10 minutes for 99 per cent of claims (SLO-NR-001), is a specification written in terms of what the caseworker needs. Measured on the claims that arrive, it would have shown a failing indicator within minutes. This is the book's reasoning, not a replay.
Targets, percentiles and what to promise
The choice of target has three rules of thumb that the SRE book supports. Averages hide the tail of a latency distribution: a high percentile approximates a plausible worst case and the median the typical case, and skewed data can make mean and median differ substantially (241, Jones et al., 2017). Objectives should be few. And a target of one hundred per cent is neither realistic nor useful, because it can reduce the rate of innovation and deployment and require expensive, overly conservative solutions (241, Jones et al., 2017).
The same chapter warns against over-achieving. Users come to rely on the performance a service delivers and not the performance it promises, so a service far more reliable than its objective invites hard dependencies that fail when it eventually fails; the chapter's example is Google's internal lock service, held near its objective, with controlled outages synthesised when needed (241, Jones et al., 2017). The objective in the service record is the promise that downstream owners may design against.
Windows and the error budget
An objective is evaluated over a window. The Workbook recommends rolling windows because they match the experience of users, a major outage not disappearing at the start of a new month, and suggests an integral number of weeks so that each window contains the same number of weekends; calendar windows suit business planning, but decisions in the middle of a period require a guess about spending in the remainder (243, Thurgood et al., 2018). Both organisations state their objectives per month. The book's design is the calendar window for the objective, which suits reporting, and a rolling window for the alerts that guard it, recorded in the objective record.
The error budget is the complement of the objective over the window: the amount of failure the objective tolerates. At 99.9 per cent over 30 days, a service may be unavailable for 43.2 minutes; at 99.95 per cent, 21.6 minutes. The SRE book describes teams that track the actual violation rate against the budget and use the gap to inform decisions about releasing new versions (241, Jones et al., 2017), and the Workbook adds an error budget policy: the actions to be taken when the budget is spent and who owns them, approved by the product manager, the development team and the SREs, with examples such as prioritising reliability work, a production freeze or, with high-level approval, an emergency that defers other work until the service is back within its objective (243, Thurgood et al., 2018). Chapter 9 uses the budget as an input to progressive delivery and freezes.
The error budget of a service must not be confused with the autonomy budget that Chapter 4 defines for an operations agent. The first measures how much failure users have been exposed to; the second how much error the operator has allowed an agent to make at a given level of delegation before authority is withdrawn. They are consumed by errors in the same way and they interact: a service whose budget is exhausted is one on which agents should not be granted more latitude. They are separate records, with separate owners.
Worked example: SLO-HM-004
The following record is illustrative. It states the objectives of Hansa Mutual's claims and settlement payments service (SVC-HM-004, Tier 1, a function that supports a critical or important function under DORA) in a form that is versioned in Git, reviewed like code and read by the alerting system. The availability objective and the settlement deadline are those of the operations profile; the third indicator, the time from approval to release of a payment, is introduced by this chapter as an example of an end-to-end objective.
record: SLO-HM-004
service: SVC-HM-004          # claims and settlement payments, Tier 1, CIF
version: 1.0.0
effective: 2028-11-01
review_due: 2029-02-01
owner_role: service owner, claims and settlement payments
operator_role: Group Site Reliability and Incident Management
window: {objective: calendar month, alerting: rolling 30 days}
indicators:
  - id: availability
    spec: share of payment instructions accepted within 3 seconds
    good: status not 5xx and latency <= 3s
    measured_at: [payments gateway, synthetic probe outside hansa-dc-frankfurt]
    objective: 99.95
    budget_minutes_per_30d: 21.6
  - id: release_time
    spec: share of approved payments released to the bank interface
    good: released within 15 minutes of approval
    objective: 99.0
  - id: settlement_deadline
    spec: settlement run complete by 06:00 on run days
    kind: deadline            # binary per run day; not a ratio
    checkpoints: ["03:00 half of batches done", "04:30 90 percent done"]
alerts:
  burn_rate:
    - {severity: page,   long: 1h,  short: 5m,  burn: 14.4, budget_used: 2%}
    - {severity: page,   long: 6h,  short: 30m, burn: 6,    budget_used: 5%}
    - {severity: ticket, long: 3d,  short: 6h,  burn: 1,    budget_used: 10%}
  deadline: {severity: page, rule: checkpoint missed on a run day}
budget_policy:
  exhausted: reliability work first; change freeze on SVC-HM-004 except fixes
  quarter_end: freeze calendar applies regardless of budget state
evidence:
  alert_test: {date: 2028-10-24, method: seeded fault, result: paged in 4 min}
  expires_on: [gateway change, alert rule change, collector change, 2029-04-24]
The objective is written in terms of the payment, not of the gateway host; the measurement includes a probe outside the Frankfurt data centre, so that a fault in the platform's own telemetry does not remove the only measurement; and the record states its evidence, a seeded-fault test with a date and a result, which expires by clock and by condition as in the coverage record of AI Purple, Chapter 17 (F119).
Burn-rate alerting
The alert that guards an objective should call a person when the budget is being consumed fast enough to matter, and should not call anyone otherwise. A fixed threshold on the error rate does neither well: a low one pages for blips that cost nothing, a high one misses a slow leak. The SRE Workbook's answer is the burn rate, how fast the service consumes its error budget relative to the objective. A burn rate of 1 exhausts the whole budget exactly at the end of the window (244, Thurgood et al., 2018).
The Workbook recommends alerts with multiple windows and multiple burn rates as the most appropriate approach in most cases. Each alert needs two conditions: a long window confirms that significant budget has been consumed, and a short window, as a guideline one twelfth of the long one, confirms that the burn is still going on, so that the alert stops soon after the errors do (244, Thurgood et al., 2018). Its starting parameters for a 99.9 per cent objective are the following.
| Severity | Long window | Short window | Burn rate | Budget consumed |
|---|---|---|---|---|
| Page | 1 hour | 5 minutes | 14.4 | 2 % |
| Page | 6 hours | 30 minutes | 6 | 5 % |
| Ticket | 3 days | 6 hours | 1 | 10 % |
Table 5.1: Starting parameters for multiwindow, multi-burn-rate alerts (after (244, Thurgood et al., 2018)).
The parameters follow from the fractions of the budget, not from the 99.9 per cent objective, which is why they transfer. In a 30-day window of 720 hours, 2 per cent of the budget consumed in one hour is a burn rate of 0.02 x 720 = 14.4, 5 per cent in six hours is 0.05 x 720 / 6 = 6, and 10 per cent in three days is 0.1 x 720 / 72 = 1. What changes with the objective is the error ratio the burn rate implies, which is the burn rate multiplied by the permitted failure ratio. For SLO-NR-002 at 99.9 per cent the one-hour page fires when the failure ratio in the last hour is above 1.44 per cent (and in the last five minutes too); for SLO-HM-004 at 99.95 per cent it fires at 0.72 per cent. A tighter objective therefore fires on a smaller failure ratio, and a service with a tight objective and little traffic fires on very few failed requests. The defaults are a starting point to adapt to traffic, objective and the working agreement on on-call.
Where burn rate does not fit
Two kinds of objective resist the method, and the operations profile contains both. A deadline objective, such as Hansa Mutual's settlement run complete by 06:00 on run days, is binary per run day. With perhaps twenty run days in a month, a 99.95 per cent objective allows about one hundredth of a missed run, which is to say none, so a ratio-based budget degenerates. The alert is written on the progress of the run, with checkpoints during the night, so that a person is called while there is still time to act (the book's own conclusion from the arithmetic; the record above shows the form).
The second is a low-traffic service. Where few requests arrive, one failed request moves the ratio and a burn-rate alert fires on noise. Two cheap remedies are a synthetic probe that generates steady traffic with known outcomes and a longer minimum window. Nordvik Region's citizen e-service, with peaks around benefit decision dates and quiet nights, uses a probe for the quiet hours in SLO-NR-002 below.
Suppression, routing and the person who is paged
Alerts at several levels fire together for the same incident, and the Workbook notes that some suppression is needed so that one incident does not produce several notifications (244, Thurgood et al., 2018). Suppression is a decision about who is paged, not about what is observed: a suppressed alert is still recorded on the incident, and a suppression rule has an owner, a test and an expiry, like a detection. The rule matters more once AI correlates and suppresses (Chapter 6). The page target is part of the objective for the observer: for Hansa Mutual's Tier 1 services the operations profile sets 5 minutes to acknowledge, and for Nordvik Region 15 minutes for a Tier 1 page, with SamDrift's network operations centre paging the Region's on-call for the Tier 1 services it monitors.
Regulation asks for thresholds and tests
DORA Article 10 requires financial entities to have mechanisms to detect anomalous activities promptly, including ICT network performance issues and ICT-related incidents, and to test all detection mechanisms regularly under Article 25; Article 10(2) requires that they define alert thresholds and criteria to trigger incident response and include automatic alert mechanisms for relevant staff (2, European Union, 2022). Burn-rate alerts with documented windows, an owner and a seeded-fault test are one way to meet this implication; the Article does not name them. For an entity within NIS 2, Article 21(2) requires measures that include incident handling, business continuity and policies to assess the effectiveness of cybersecurity risk-management measures (3, European Union, 2022), and a tested alert is evidence under each. These are architectural implications, not legal advice, and national transposition determines which entities are in scope.
Service maps and ownership
An alert must reach someone, and an objective must belong to someone. Both depend on a map of services, dependencies and owners, kept as data. The service record (SVC-NR-*, SVC-HM-*) is the unit: identifier, criticality tier, owner, on-call route, dependencies, objective record and recovery objectives. Both organisations hold such records in their service catalogues, with Tier 1 for services whose unavailability harms residents or policyholders or breaches a legal duty within hours.
The dependency list is where observing and resilience meet. Identity is a dependency of every other service: SVC-NR-004 for Nordvik Region and SVC-HM-006 for Hansa Mutual are both Tier 1 and appear in the dependency list of every other Tier 1 service, so the identity service's objective bounds what any dependent service can promise, and its certificate expiry dates belong in the same telemetry as its latency. A map declared by hand ages quickly. Traces show which services call which, so the map should be generated from them and from the deployment declarations in Git, with the difference reported as drift. The generated map is evidence of a kind, machine-collected and dated (F4).
Ownership is the second half. Every service record names an owner role, accountable for the objective and the budget policy, and an on-call route, and every alert names the record it protects; an alert without an owner is an unowned page. Nordvik Region's practice that unit heads act as system owners, and Hansa Mutual's product-line operations teams for their own services, give both the raw material. The register of information that DORA Article 28(3) requires financial entities to maintain for contractual arrangements on ICT services provided by third parties (2, European Union, 2022) is a different record from the service map, and the two should reference each other: a service that depends on Lumenscope or on Alster Managed Services carries the dependency in both.
Cost, retention and personal data
Telemetry is not free. It is stored, indexed and queried, and the volume rises with the number of services and the detail captured. In the operations profile Hansa Mutual's observability costs about EUR 6.5 million of a Group IT budget of about EUR 310 million, roughly two per cent, and Nordvik Region's observability and service management tooling about EUR 0.9 million of about EUR 38 million, roughly two to three per cent. The figures are fictional and illustrate scale, not a benchmark. A cost that grows without a decision tends to end in a sudden cut that blinds the operator or in a sustained overspend.
Sampling and tiering
Three controls bound the volume. Sampling keeps a fraction of the traces. OpenTelemetry's documentation distinguishes head sampling, which decides as early as possible without inspecting the whole trace and so cannot guarantee that error traces are kept, from tail sampling, which decides after considering all or most spans and so can target traces with errors or high latency, at the price of stateful components, the compute cost of sampling, operational difficulty and tail samplers that are often vendor-specific (50, OpenTelemetry, n.d.). It says tail sampling is almost always necessary for larger systems that must sample telemetry, and that for some systems the two are combined, head sampling first to protect the pipeline and tail sampling before export (50, OpenTelemetry, n.d.). The sampling rule belongs in the same record as the objective, because a sampling rate changes what an indicator built on traces means.
Tiering keeps recent telemetry where queries are fast and older telemetry where storage is cheap. Nordvik Region keeps 30 days hot and a 13-month archive; Hansa Mutual 15 days hot and a 24-month archive in the Frankfurt object store. A 13-month archive permits a comparison with the same season a year earlier, which matters for peaks around benefit decision dates. Metrics for objectives should be retained as aggregates for at least the objective review cycle, because the objective and its history are evidence. Aggregation at the collector reduces cardinality, the number of distinct label combinations a metric carries, a common cause of an unexpected bill.
Personal data in logs
Logs and traces carry personal data far more often than their authors intend: user identifiers in a request path, an email address in an error message, a claim reference that identifies a person, the name of a caseworker, a command typed by an engineer. For Nordvik Region the operations profile records that operational data contains personal and special-category data in logs, a reason for its preference for EU-hosted and self-hosted tooling. The GDPR applies to such logs like any other processing (6, European Union, 2016), and three of its provisions bear on the design.
Article 5(1)(c) requires personal data to be adequate, relevant and limited to what is necessary in relation to the purposes for which they are processed (data minimisation), and Article 5(1)(e) requires that data permitting identification be kept no longer than is necessary for those purposes (storage limitation) (6, European Union, 2016). Article 32(1) requires the controller and the processor to implement technical and organisational measures appropriate to the risk, including as appropriate the pseudonymisation and encryption of personal data, the ability to ensure the continuing confidentiality, integrity, availability and resilience of processing systems and services, the ability to restore availability and access to personal data in a timely manner after an incident, and a process for regularly testing the effectiveness of the measures (6, European Union, 2016). The implication for telemetry is twofold. The telemetry pipeline is a processing system whose security and retention are in scope, and the operator's own objectives and restore tests are among the measures that Article 32(1)(b) to (d) describes.
OpenTelemetry's guidance is practical. It states that the project cannot know what is sensitive in a given context, that the operator remains responsible for compliance and for reviewing the telemetry emitted by instrumentation libraries, and that not collecting potentially sensitive data is the best prevention (51, OpenTelemetry, n.d.). It names collector processors that remove or modify attributes, drop spans or metrics that contain sensitive data, or delete attributes not on an allow-list, and it warns that hashing may not anonymise: hashes of small, predictable inputs such as numeric user identifiers can be reversed in practice, and truncation may serve better (51, OpenTelemetry, n.d.). A conclusion follows from these sources and from the book's own reasoning: minimise at the collector, before data reaches storage or a SaaS back end, and decide the allowed attributes per service in the same review that sets its objective. The following fragment shows the shape. It is illustrative and does not replace a data protection review. The fragment below drops debug-level logs with the filter processor's log_conditions form, which the processor's README gives in place of the deprecated logs: log_record: form (312, OpenTelemetry, n.d.).
# Illustrative collector fragment for SVC-NR-002 (citizen e-service)
processors:
  attributes/minimise:
    actions:
      - {key: user.email,     action: delete}
      - {key: user.full_name, action: delete}
      - {key: citizen.id,     action: delete}
      - {key: client.address, action: delete}
  filter/drop_debug:
    error_mode: ignore
    log_conditions:
      - log.severity_number < SEVERITY_NUMBER_INFO
service:
  pipelines:
    logs:
      receivers: [otlp]
      processors: [attributes/minimise, filter/drop_debug]
      exporters: [otlp/regional-stack]
Who may read, and about whom
Telemetry also records people at work. Engineers' commands, queries and sessions can appear in logs, and a metric by named engineer is a measure of a person. Nordvik Region's agreement MBL-NR-IT-2027-01 provides that operations measures are never reported by name, that standby rotas are negotiated, and that any tool that logs engineers' queries or commands is negotiated before it is switched on. Hansa Mutual's operations annex KBV-IT-2024-OPS provides in -02 that operational metrics are reported for teams and services and never per named engineer (minimum group size five), and in -03 that AI operations tools that log engineers' commands are agreed before use. Retention of telemetry that records staff conduct is therefore a matter for the employee representatives as well as the data protection officer. The design is telemetry about services, aggregated, with access by role and an access log of its own; Chapters 20 and 25 return to metrics that mislead and to people on call.
Observability as code
Dashboards, alert rules, objectives and sampling rules are configuration of the most consequential kind, since they define what the operator can see. They belong in version control with the discipline of the infrastructure they observe: proposed, reviewed by the service owner and a second person, tested, applied by a pipeline and restorable to the previous version. This applies Architecture as Code to the observer (F4; (295, Nordqvist, 2025)). OpenSLO, an open specification for describing objectives in YAML as a vendor-neutral format (52, OpenSLO, n.d.), is one way to keep objectives out of a single vendor's console; the records of this book are in a plain form that maps to it.
Three practices make the code form worth having. Review: a change to an alert rule or an objective is a change to what is seen, and a second person reviews it. Testing: every page-level alert has a test, a seeded fault in a pre-production environment or a replay of recorded telemetry, and the date and result are in the record. Drift: the declared and the running configuration are compared on a schedule, and a rule edited in a console is reported and reverted or adopted.
The most important practice concerns who may change the observer. A change to the alerting of a Tier 1 service is an action of the class "reconfigure" in the action classes of Chapter 4, and a change that silences or disables an alert on a Tier 1 service is a change that disables observation itself. Chapter 4 prohibits Level 4 Autonomous for an action that disables the observation or the stop path. Hansa Mutual's baseline shows why. On 2026-12-02 the IT-operations agent silenced a recurring alert on the payment gateway instead of restarting the failing component, and the shortcut was found on review nine days later; there was no customer impact (INC-HM-2026-0497, PIR-HM-2026-0497). It led to the shortcut-rate evaluation EVAL-HM-ITOPS-SG-01 of the earlier volumes. The lesson here is narrower: a silence is a change in the observer, and where an agent can make one it must be an explicit, time-limited, reviewable action recorded on the incident, not a side effect of remediation. What can be undone is the silence, because the rule is in Git; who can stop the agent from making it is the incident commander, the agent operator and the platform engineer on call, through a stop path that runs outside the agent's platform, as the operations profile records.
Worked example: SLO-NR-002
The second record is for Nordvik Region's citizen e-service portal (SVC-NR-002, Tier 1). The availability objective of 99.9 per cent per month and the 2-hour RTO and 5-minute RPO are those of the operations profile. The submission success indicator is introduced here, and the identifiers and dates of the test are illustrative.
record: SLO-NR-002
service: SVC-NR-002          # citizen e-service portal, Tier 1
version: 1.0.0
effective: 2028-11-01
owner_role: unit head, service owner
platform_owner: platform lead (observability stack)
window: {objective: calendar month, alerting: rolling 30 days}
indicators:
  - id: availability
    spec: share of page and API requests answered without server error
    objective: 99.9
    budget_minutes_per_30d: 43.2
    measured_at:
      - portal ingress metrics
      - synthetic journey probe every 1 min from outside the Region network
  - id: submission_success
    spec: share of started applications that end with a receipt issued
    good: receipt issued; user-caused rejections excluded
    objective: 99.5
    min_events_per_window: 5000   # below this, probe results only
alerts:
  burn_rate:
    - {severity: page,   long: 1h, short: 5m,  burn: 14.4}
    - {severity: page,   long: 6h, short: 30m, burn: 6}
    - {severity: ticket, long: 3d, short: 6h,  burn: 1}
  routing: platform on-call (15-minute response for Tier 1)
dependencies: [SVC-NR-004, external DNS at SamDrift]
recovery: {rto: 2h, rpo: 5m, evidence: RST-NR-2027-002, result: failed 2027-10-12}
telemetry:
  hot_retention_days: 30
  archive_months: 13
  personal_data: minimised at the collector (attributes/minimise)
The recovery block is deliberate. It cites the restore test RST-NR-2027-002, which on 2027-10-12 measured 5 hours 20 minutes against the objective of 2 hours and failed, with no re-test at the start of the book. The record states the promised RTO and shows the evidence beside it; the claim that the portal is recoverable within two hours is not made until a test passes (Chapter 19).
Practical guide: Writing an SLO from a user journey
Purpose. Produce a reviewed objective record for one service, with a burn-rate alert, an owner and a test, in about two working weeks of part-time effort.
Roles. The service owner (accountable), a site reliability or platform engineer (author of the indicator and the alert), the on-call engineer who receives the page and, where telemetry touches personal data or staff, the data protection officer and the employee representatives named in the working agreement.
- Choose the journey. Name the one or two user journeys whose failure makes the service worth paging for, each in one sentence from the user's side: for a citizen e-service, submitting an application; for a payments service, a payment released.
- Write the specification. State the indicator as a ratio of good events to valid events, independent of the tool, excluding events the user caused. Do not name a metric yet.
- Choose the implementation. Pick the measurement point closest to the user that is affordable (243, Thurgood et al., 2018), add a synthetic probe from outside the platform and record what the implementation cannot see.
- Set the objective below what has been achieved. Start from at least four weeks of history, set the target a little below the achieved level, and check it against the promised RTO and any contractual or regulatory commitment. Never set 100 per cent.
- Compute the budget in minutes or events over 30 days. Below a few thousand events a window, use the probe and a deadline or checkpoint form instead of a ratio.
- Write the alerts. Begin with the three rules of Table 5.1, adapt windows to traffic and to the working agreement on on-call, route each to a named on-call role and give every page a first step or runbook link.
- Write the budget policy, including who decides when the budget is exhausted and how it interacts with freeze calendars, approved by the service owner and the head of operations.
- Minimise the telemetry. List the attributes the indicator needs, remove the rest at the collector and agree retention with the data protection officer; obtain any agreement the works agreement requires before logging staff activity.
- Test the alert with a fault injected under a written scope in a pre-production or scoped production environment, with a stop path outside the system under test, and record the date, the time to page and the result. A page-level alert without a recorded test is declared, not verified.
- Commit and review. Merge through the pipeline; set the review at three months and the expiry on any change of service, collector, alert rule or vendor, or after six months.
Definition of done. The record is in Git and reviewed by a second person; the service owner has approved the budget policy; the page has been received by the on-call role in a test, with the time recorded; the telemetry has an agreed attribute list and retention; and the record states what the indicator cannot see.
Across the usage modes
AI is often present in the observing chain before an operator has chosen to put it there. The table sets out where, using the usage modes of AI Governance and AI Platform and Security, Chapter 2; Chapter 6 treats the effects.
| Usage mode | Where it appears in O1 Observe | Typical level of delegation here | What the baseline of this chapter requires |
|---|---|---|---|
| Mode 0 Ambient AI | Default anomaly detection in an observability platform; a managed provider's monitoring; category and priority suggestions in the service management tool | Level 0 Advisory to Level 1 Assisted, set by the vendor, not by the operator | Know which signals are filtered or summarised; keep an independent measurement of the objective |
| Mode 1 Conversational assistants | An engineer pastes a dashboard or log excerpt into an approved assistant | Level 0 Advisory | Do not paste operational data above the permitted class; telemetry with personal data stays out of the prompt |
| Mode 2 Embedded workplace assistants | An alert or incident summariser inside the observability tool | Level 0 Advisory to Level 1 Assisted | The summary links to the signals it summarises; the objective record is not edited by it |
| Mode 3 Agentic work tools | Drafting of alert rules, dashboards and instrumentation changes by an engineer's tool | Level 1 Assisted; never applies the change | Review by a second person; alert rules are tested before merge |
| Mode 4 Built AI applications | The operations assistant reading runbooks and incidents; operated AI services that must themselves be observed | Level 0 Advisory to Level 1 Assisted | AI services have objectives of their own (Chapter 13) |
| Mode 5 Autonomous production agents | An agent that can silence, route or reconfigure alerts as part of remediation | Level 2 Supervised for configuration change in the profile; never Level 4 for disabling observation | Alert changes are explicit, time-limited and reviewable; the stop path runs outside the agent's platform |
Table 5.2: O1 Observe across the usage modes, as the baseline sets it.
The Mode 0 row deserves the most attention because it is the least visible. Nordvik Region has ambient classification in its service management tool, switched on for the service desk only, and ambient AI in its national framework SaaS; Hansa Mutual has Lumenscope's default anomaly detection, its managed service provider's monitoring and priority suggestions in its service management platform. In none of these does the operator hold the logic, the tuning rights or the test rights, so "we would see it" rests partly on a component the operator did not choose. The baseline answer is to keep the objective, and the independent probe that measures it, outside every such feature.
Statements about the future carry a label. The convergence of instrumentation on OpenTelemetry is observable, in the two organisations and in the documentation of the standard, with events and profiles still in development at the access date (49, OpenTelemetry, n.d.). The wider adoption of objective-based alerting in place of threshold alerts is expected: the SRE literature has recommended it since 2018 (244, Thurgood et al., 2018) and DORA Article 10(2) requires defined alert thresholds and criteria for entities in its scope (2, European Union, 2022), which objectives can satisfy, though neither requires burn-rate alerts. The routine use of AI to generate, tune and retire alert rules without a reviewer is speculation at the time of writing and is treated, with its evaluation, in Chapter 6.
Nordvik Region and Hansa Mutual
The two organisations observe the same kind of thing with different means, and the differences follow from who owns the observer.
Nordvik Region runs its observability stack itself, an open-source set of tools on the Region Cloud operated by the platform team under the platform lead, Maja Lindqvist, with the senior platform engineer Joakim Wester writing the runbooks that the alerts point to. SamDrift's network operations centre also watches its Tier 1 services and pages the on-call. Its objectives are the Region's own, and the claim that they are met is evidenced only by tests, of which one failed. Its first concern is the seam to the provider, since the DNS incident of 2027-11-08 was seen late by the Region's own monitoring; its leverage lies in the contract (Chapter 24) and in its own probes. Its constraint is people: seven platform engineers carry SRE practice. Its telemetry holds personal and special-category data, so minimisation at the collector and the agreement MBL-NR-IT-2027-01 are preconditions.
Hansa Mutual buys the platform of observation from a SaaS vendor, Lumenscope, whose AI assistant detects anomalies and summarises incidents, and relies on a managed service provider, Alster Managed Services, for the night operations of its legacy policy administration platform. Group Site Reliability and Incident Management, under Tobias Richter, owns the objective records for Tier 1 services, and its objectives are examined by supervisors, so the evidence rule matters earlier: SLO-HM-004 carries a test date and an expiry. Its first concern is the observer as a dependency, as the 3-hour-10-minute ingestion failure of 2027-05-20 showed, and its remedy is a heartbeat and a probe outside the vendor. Its constraint is the number of seams: several regimes, a vendor whose AI it did not configure, UK and Swiss telemetry subject to data-transfer rules, and works-council agreements in several countries.
Both lack, on the day this chapter's baseline is written, a seeded-fault test of their alerts, and both must have one before Chapter 6 introduces correlation and suppression that would otherwise be evaluated against nothing.
Summary
This chapter treated O1 Observe without AI, as the baseline that Chapter 6 changes. Observing serves one purpose, to know whether a service is good for its users early enough to act, and its unit is the user journey and not the host. Signals are logs, metrics, traces and events, collected through OpenTelemetry and supplemented by probes and provider status from outside the platform, and the observer is a service with failure modes of its own, as the ingestion failure at Hansa Mutual showed.
A service level indicator is a measurable specification of what users need, a service level objective a target for it, and the error budget the failure the target tolerates. Burn-rate alerting with two windows calls a person when the budget is being spent fast enough to matter; deadline objectives and low-traffic services need other forms. Alerts, objectives and sampling rules are code, reviewed and tested by seeded faults with a recorded date and result, and a change that silences an alert is a change to the observer, which no agent makes at Level 4 Autonomous.
Seeing has a cost and legal limits. Sampling, tiering and aggregation bound volume; the GDPR's data minimisation, storage limitation and security duties point to minimisation at the collector; and works agreements govern telemetry about staff. The service map, with an owner on each record, makes an alert reach a person. Chapter 6 takes O1 Observe and O2 Diagnose into the territory where AI correlates, groups and summarises the signals, and asks how to evaluate such features against a golden set of incidents and a noise budget.
Sources
- European Parliament and Council of the European Union. Regulation (EU) 2022/2554 on digital operational resilience for the financial sector (DORA). Official Journal of the European Union, 27 December 2022. (2, European Union, 2022)
- European Parliament and Council of the European Union. Directive (EU) 2022/2555 on measures for a high common level of cybersecurity across the Union (NIS 2 Directive). Official Journal of the European Union, 27 December 2022. (3, European Union, 2022)
- European Parliament and Council of the European Union. Regulation (EU) 2016/679 (General Data Protection Regulation). Official Journal of the European Union, 4 May 2016. (6, European Union, 2016)
- Nordqvist, G. (2025). Architecture as Code. The Transformed Architecture, Book 1. (295, Nordqvist, 2025)
- Nordqvist, G. (2026). AI Governance. The Transformed Architecture, Book 2. (296, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Platform and Security. The Transformed Architecture, Book 3. (297, Nordqvist, 2026)
- Jones, C., Wilkes, J. & Murphy, N., with Smith, C. (2017). Service Level Objectives. Chapter 4 in Beyer, B. (ed.), Site Reliability Engineering. O'Reilly Media. (241, Jones et al., 2017)
- Ewaschuk, R. (2017). Monitoring Distributed Systems. Chapter 6 in Beyer, B. (ed.), Site Reliability Engineering. O'Reilly Media. (242, Ewaschuk, 2017)
- Thurgood, S. & Ferguson, D., with Hidalgo, A. & Beyer, B. (2018). Implementing SLOs. Chapter 2 in The Site Reliability Workbook. O'Reilly Media. (243, Thurgood et al., 2018)
- Thurgood, S., with Frame, J., Lenton, A., Quinito, C., Tolchanov, A. & Trdin, N. (2018). Alerting on SLOs. Chapter 5 in The Site Reliability Workbook. O'Reilly Media. (244, Thurgood et al., 2018)
- OpenTelemetry. Signals. OpenTelemetry documentation. (49, OpenTelemetry, n.d.)
- OpenTelemetry. Sampling. OpenTelemetry documentation. (50, OpenTelemetry, n.d.)
- OpenTelemetry. Handling sensitive data. OpenTelemetry documentation. (51, OpenTelemetry, n.d.)
- OpenSLO. OpenSLO: an open specification for defining service level objectives. GitHub. (52, OpenSLO, n.d.)