Measuring Operations: The Four Key Metrics, SLOs, Toil and the Metrics That Mislead
An operations organisation is steered by what it measures. A number on a dashboard decides where engineers spend the quarter, whether a release goes out on Friday, whether a recovery objective is believed and whether an agent keeps the permissions it was given. This chapter concerns all five operations functions defined in Chapter 4: O1 Observe, because every measure is computed from telemetry; O2 Diagnose, because incident durations describe how diagnosis went; O3 Change, because the best-known operations metrics describe the change pipeline; O4 Restore, because time to restore and the evidence for recovery measure it; and O5 Sustain, because toil, cost and the condition of the operators are measured over months and years. The chapter sets out which metric informs which decision, how each one misleads, and what a definition must contain so that the misuse is written down before it happens.
The argument has three parts. A metric is justified by the decision it informs. The usual operations measures fail in predictable ways: means hide tails, ratios hide missing data, counts reward volume, and any measure that becomes a target is optimised, which AI makes cheaper and faster. And the measures that matter for this book's thesis are new ones, such as the consumption of the autonomy budget, the share of actions verified by an observer independent of the actor and the age of the evidence for a recoverability claim; the chapter defines them with the same care as the standard ones.
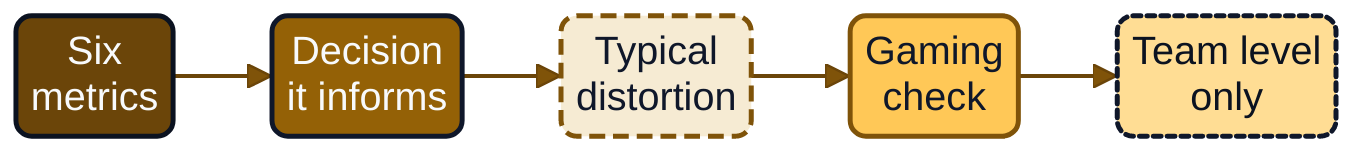
Figure 20.1: Metrics, decisions, distortions and checks, in one chain. The table in the text gives the rows.
The chapter builds on the earlier volumes. AI Blue, Chapter 20, replaced time to detect, time to respond and closure counts with four families of measure, each with a gaming check, and fixed the rule that measures about people are agreed first and reported in aggregate (F105) (302, Nordqvist, 2026). AI Purple, Chapter 18, described Goodhart's law in four forms and recorded that a green percentage without a denominator misleads (F132). AI Boss, Chapters 11 to 15 and 26, supplied the measurement of oversight quality, with the rule that an approval given in seconds is a signal of failure (F84), and the quiet harms of monitoring staff (F89) (301, Nordqvist, 2026).
What a metric is for
A metric is a question asked repeatedly. Before it is computed, someone must be able to say which decision it informs, who takes that decision, and what the decider does differently when the number moves. A metric with no such statement consumes collection effort and invites management by whichever number happens to be available.
Every metric in this chapter is described by the same six properties, and the practical guide later in the chapter turns them into a template.
- The decision. The choice the metric informs, such as whether to freeze releases or to raise or lower an agent's level.
- The definition. A numerator, a denominator, a window and, for anything timed, the event that starts the clock and the event that stops it. Two teams that start the clock at different events measure different things under one name.
- The source. The system the data comes from, and whether it is independent of the thing measured. A service level computed from the telemetry pipeline whose failure it should reveal has a shared failure domain. This is the observer principle of Chapter 4 applied to measurement: what verifies must be independent of what performed, and the observer must not depend on the system observed.
- The form of reporting. A single number, a distribution, a count beyond a threshold or a list of named incidents. The same data supports different conclusions in different forms.
- The misuse notes. How the metric is known to mislead, the gaming it invites and the check that detects each.
- The subject. In this book always a service, a pipeline, a delegation or a team, and never a named person.
The last property needs a reason. AI Blue, Chapter 21, concluded that measures concern the system and not the person, and that tools which log every query can profile an individual and fall within co-determination (F110); in German law a tool that logs every query is objectively suited to record behaviour and so falls within section 87(1) number 6 of the Betriebsverfassungsgesetz (26, Germany, n.d.); (311, Bundesarbeitsgericht, 2024). A median restore time for a team of eleven on-call engineers describes a rota and its runbooks. A restore time per engineer describes a person at the worst moment of a working week, means little at such sample sizes, and changes what the engineer does at the next incident.
The four key metrics
The research programme that popularised the best-known delivery measures in operations is the DevOps Research and Assessment (DORA) programme, run by Google Cloud. The abbreviation collides with Regulation (EU) 2022/2554, which this book calls DORA throughout, so this is the only place the programme is named by its abbreviation; from here it is "the four key metrics". The programme's research was set out for a general readership in Accelerate (267, Forsgren et al., 2018), and the programme maintains a guide to the measures that the chapter relies on for definitions (268, DevOps Research and Assessment programme, n.d.).
What they measure
The guide divides software delivery performance into throughput and instability. Throughput is measured by change lead time, the time for a change to go from committed to version control to deployed in production, by deployment frequency, and by failed deployment recovery time, the time it takes to recover from a deployment that fails and requires immediate intervention. Instability is measured by the change fail rate, the ratio of deployments that require immediate intervention following a deployment, and by the deployment rework rate, the ratio of deployments that are unplanned but happen as a result of an incident in production (268, DevOps Research and Assessment programme, n.d.). The guide now counts these five measures and records that its original model had four; this book keeps "the four key metrics" as the name of the group. The guide records the programme's own cautions: mandating a metric as a goal increases the likelihood that teams will try to game it (it cites Goodhart's law), several metrics with some tension between them are better than one, comparing metrics between vastly different applications can mislead, and the goal is to improve a team's performance over time and not to compete against other teams.
Three limits follow from the definitions; they are the book's reading and not the programme's.
First, the four key metrics describe the change pipeline, so they belong chiefly to O3 Change, with failed deployment recovery time reaching into O4 Restore. A service can have an excellent lead time and a poor availability, and the reverse.
Second, failed deployment recovery time is not the time to restore of all incidents. An outage caused by a storage controller, an expired certificate or a provider's DNS fault does not appear in it. Organisations that report it as the recovery performance of operations describe a subset under the name of the whole, and the programme's guide uses the narrower term for that reason.
Third, the metrics count what the pipeline sees. A configuration push through a console, a supplier's release, or a change recorded as standard that skips a canary stage is absent from the count. Hansa Mutual's INC-HM-2027-0833 is the pattern: a configuration push to the AI gateway routing broke the claims assistant in four markets for 47 minutes because a canary stage was skipped on a change classified as standard. From the first quarter of 2028 Hansa counts such pushes in its deployment events, and the rule is part of the metric definition. Nordvik Region meets the limit from the other side: INC-NR-2026-0214, in which a TriageSoft release changed a queue setting and claim ranking stalled for 5 hours 10 minutes, was a change the Region neither deployed nor counted. For supplier-run services the measure it needs is release notice, the time between the supplier's notice of a change and the change itself.
Small numbers and the denominator
Rates need denominators large enough to bear them. Nordvik Region's platform team made 62 production deployments in the fourth quarter of 2028 and three of them failed, a change fail rate of 4.8 per cent. A single further failure would have moved the rate to 6.5 per cent. A quarterly rate over a denominator this small swings by more than the improvement a programme would be expected to deliver. The Region therefore reports the counts, 62 deployments and three failures with a one-line description of each, and shows the rate only over four quarters. The DORA programme's guide advises teams to start with conversations and not elaborate integrations; at the Region's scale that advice is a design rule.
What AI changes
AI changes the measured quantities in two ways. The first is volume. When coding agents and infrastructure assistants author much of the change (Chapter 8), deployment frequency rises and change lead time falls without any improvement in what the deployments are worth. The second is stability, where the large-scale evidence is the programme's own survey. Google Cloud's summary of the 2024 report, based on annual surveys of professionals in technical roles, states that as AI adoption increased it was accompanied by an estimated decrease in delivery throughput of 1.5 per cent and in delivery stability of 7.2 per cent, alongside improvements in documentation quality, code quality and code review speed for each 25 per cent increase in adoption (251, Harvey & DeBellis, 2024). The summary does not state the adoption increase to which the throughput and stability figures correspond, and the data are survey associations, so they are observable as an association and not as a cause.
A randomised trial shows why perceived and measured performance must be kept apart. Becker and colleagues had 16 experienced open-source developers complete 246 tasks on their own repositories, each task randomly assigned to allow or disallow early-2025 AI tools. Developers had forecast a 24 per cent reduction in completion time and, afterwards, estimated a 20 per cent reduction; the measured effect was an increase of 19 per cent (231, Becker et al., 2025). The study concerned software development by experienced maintainers, not operations. Its value here is the gap between belief and measurement: a survey of how much faster operators feel with an incident assistant measures feeling, and where a decision such as promotion of an agent depends on the effect, it is measured against a comparison.
SLO attainment and error budgets
A service level objective (SLO) is the measure operations adopted from site reliability engineering (SRE) for what good means. The Google SRE book defines a service level indicator (SLI) as a carefully defined quantitative measure of some aspect of the level of service provided and an SLO as a target value or range of values for a service level measured by an SLI (241, Jones et al., 2017). The SRE workbook recommends treating the SLI as the ratio of two numbers, good events divided by total events, and choosing a small number of SLI types, five or fewer, that cover the most critical functionality (243, Thurgood et al., 2018). Chapter 5 treats their construction. This chapter concerns what the attainment figure is used for and how it misleads.
From attainment to decision
Attainment is the SLI over the window compared with the objective. The error budget is the permitted shortfall, and the decision it informs is the allocation of risk: while budget remains, change proceeds; when it is exhausted, something else happens. The SRE workbook says that to make error budget enforcement decisions one must start with a written policy, and lists typical responses: engineering gives priority to reliability bugs, the team works only on reliability until the service is within its objective, or a production freeze halts certain changes until budget returns. It adds that the policy should name who takes these actions and provide an escalation path (243, Thurgood et al., 2018). The policy is therefore part of the metric. An attainment figure with no written consequence is a status report.
Burn rate turns the budget into an alerting signal: the workbook defines it as how fast, relative to the SLO, the service consumes the error budget. For a 99.9 per cent objective it recommends multiwindow, multi-burn-rate alerts: a page when 2 per cent of the budget is consumed in one hour (burn rate 14.4, five-minute short window), a page at 5 per cent in six hours (burn rate 6, 30-minute short window) and a ticket at 10 per cent in three days (burn rate 1, six-hour short window) (244, Thurgood et al., 2018). These are starting points for that objective, adapted to each service's objective and tolerance for noise.
How attainment misleads
Four distortions recur.
The ratio hides the shape. Seven hours of outage in one afternoon and seven hours spread over a month of two-minute blips give the same attainment and opposite meanings. Nordvik Region's SLO-NR-003 for the case-management system promises 99.5 per cent per month in working hours. If the window is 07:00 to 17:00 on working days, about 220 hours, the budget is 66 minutes, and the 7 hour 5 minute outage of 21 November 2028 described below consumed 644 per cent of it in one afternoon. The month's attainment, 96.8 per cent, was red and correctly so; the lesson is that attainment is always reported with the longest single breach beside it.
Missing data reads as good. An SLI computed from a telemetry pipeline has an implicit denominator, the events that arrived. When ingestion fails, the denominator shrinks and the ratio can stay high. Hansa Mutual's INC-HM-2027-0572 is the case: Lumenscope's ingestion failed for 3 hours 10 minutes, the group was blind on 14 services, and the vendor's status page was the only signal. The fix is a measure of the measure, a data-completeness SLI reported beside every SLO, and at least one SLI for each Tier 1 service computed from a probe that does not depend on the ingestion path, the observer of Chapters 4 and 17 in its simplest form.
The indicator is measured where it is easy. A server-side success ratio does not show a session failing at the identity provider or in DNS. Nordvik's INC-NR-2027-0298, a SamDrift DNS fault that made the e-services unreachable from outside for 70 minutes, was seen by the Region's own monitoring 22 minutes after SamDrift's status page. A detection time measured from the first alert of the Region's monitor starts the clock 22 minutes late. The clock starts at the first moment of user impact established in the post-incident review, and the gap between that moment and the first alert is itself a metric, the detection gap.
The objective moves. An SLO that is repeatedly missed invites loosening, and one that is easily met invites tightening only at review. Loosening to restore green is the simplest form of gaming and the hardest to see in a chart. The check is a change log on every objective: who changed it, when, on whose authority and with what evidence of user need.
Time to restore: the mean and the distribution
Mean time to restore (MTTR) is the most widely reported operations measure, and the statistic is poorly suited to the use made of it. The Google SRE book makes the general point about latency: most metrics are better thought of as distributions rather than averages, and a simple average can obscure tail behaviour and changes in it (241, Jones et al., 2017). Incident durations behave the same way. A report by Davidovič for Google's SRE team, using a Monte Carlo simulation and statistical analysis, argues that statistics such as MTTR and mean time to mitigation are poorly suited to decision making or trend analysis in the context of production incidents (269, Davidovič, 2021). This chapter relies only on that stated conclusion and on elementary arithmetic.
The tail incident at Nordvik Region
Nordvik Region's quarterly service report to the regional executive committee gave a mean time to restore for incidents on Tier 1 and Tier 2 services against a target of 90 minutes. For the fourth quarter of 2028 the report showed 41 incidents and a mean of 72 minutes, green.
On 21 November 2028, INC-NR-2028-0391 made the case-management system, SVC-NR-003, unavailable for 7 hours 5 minutes (425 minutes) after a database schema migration locked the database and the service was restored from the immutable store, 3 hours 5 minutes beyond its 4-hour objective. The incident was in the quarter's data and the report was green. The other 40 incidents had a mean of 63 minutes; the 425-minute incident added 9 minutes to the quarter's mean, because it was one value among 41. A 10 per cent shortening of every incident would have moved the mean by about 7 minutes. One catastrophe moved the figure by less than a modest programme's gain, and the report told the committee that operations had met its target in a quarter in which a Tier 1 service was down for most of a working day.
The committee read PIR-NR-2028-0391 in January 2029 and saw that the report had not mentioned the outage. The Region's response, AIDR-0921 (dated 2029-01-23; owner the Head of IT and Digitalisation; review by 2029-07-23), stopped the publication of a mean. The report now gives, for each tier, the median and the 90th percentile of restore time, the number of incidents that exceeded the recovery time objective (RTO) of the affected service, and every such incident by identifier with its restore time and a one-sentence cause. For Q4 2028 the median was 24 minutes, the 90th percentile 2 hours 10 minutes, and one incident exceeded its RTO. A reader now sees the 7-hour incident first and the ordinary quarter second.
The form used at Hansa Mutual
Hansa Mutual reports time to restore to its management body as a distribution. The executive board is the management body for DORA, and Article 5(2)(i) requires it to put in place, at corporate level, reporting channels enabling it to be duly informed of, among other things, at least major ICT-related incidents (2, European Union, 2022). The form, AIDR-0971 (dated 2028-10-17; owner the head of Group Site Reliability and Incident Management; review by 2029-04-17), is a page per quarter with the median and the 90th and 95th percentiles for Tier 1 services, the count of incidents above each service's RTO, the five longest incidents by identifier, and the same figures for services supporting critical or important functions. For Q4 2028 there were 96 incidents on Tier 1 services; the median was 29 minutes, the 90th percentile 1 hour 58 minutes, the 95th percentile 3 hours 5 minutes and the longest 5 hours 12 minutes. The mean, which the page does not show, would have read 52 minutes. Five incidents caused more than 2 hours of downtime on a service supporting a critical or important function.
That figure connects the operations measure to the regulatory one. Commission Delegated Regulation (EU) 2024/1772, which supplements DORA with technical standards for classifying incidents, measures duration from when an incident occurs until it is resolved and service downtime from when the service becomes unavailable until the prior service level is restored (Article 3). Article 9(3) sets the duration criterion at more than 24 hours and the downtime criterion, for ICT services that support critical or important functions, at more than 2 hours. Under Article 8(1) an incident is major only if it affects critical services and also meets the threshold for malicious, unauthorised access that may result in data losses (Article 9(5), point (b)) or at least two of the other thresholds, so exceeding the downtime threshold alone does not make it major (15, European Commission, 2024). The five Hansa incidents met the downtime criterion and none met the further conditions. The practical rule is to define the clocks of the operations metric to match the legal clocks, so that one incident does not have one duration in the operations report and another in the notification. Hansa measures restore time as the downtime of Article 3.
The instrument itself classifies by thresholds and not by means. The wider shift in supervisory reporting from means to distributions and counts beyond a threshold is expected, on the stated trend that incidents are classified and examined individually and that the arguments against the mean are now well established in operations practice.
Reporting restore time
The following Python function produces the report form both organisations use.
from statistics import median
from math import ceil

def percentile(sorted_values, p):
    """Nearest-rank percentile of an ascending list; p in (0, 100]."""
    k = max(1, ceil(p / 100 * len(sorted_values)))
    return sorted_values[k - 1]

def restore_report(incidents, rto_minutes):
    """incidents: list of (incident_id, service, restore_minutes).
    rto_minutes: dict service -> recovery time objective in minutes."""
    durations = sorted(m for _, _, m in incidents)
    over_rto = [
        (i, s, m) for i, s, m in incidents if m > rto_minutes[s]
    ]
    longest = sorted(incidents, key=lambda x: -x[2])[:5]
    return {
        "count": len(durations),
        "median_min": median(durations),
        "p90_min": percentile(durations, 90),
        "p95_min": percentile(durations, 95),
        "over_rto": sorted(over_rto, key=lambda x: -x[2]),
        "longest_five": longest,
        # No mean is reported: it is neither a decision input nor stable.
    }
The report carries no mean by design. It also carries the incident identifiers, which is what keeps a tail incident visible: a percentile alone can hide a single event as a mean can, and the list of named incidents beyond the objective cannot.
Toil and the autonomy budget
Toil
Toil is the measure of the work that operations would prefer not to do. The Google SRE book defines it as work tied to running a production service that tends to be manual, repetitive, automatable, tactical, devoid of enduring value, and that scales linearly as a service grows, and notes that toil is not the same as work that merely feels unpleasant or as overhead such as meetings. It states a goal of keeping toil below 50 per cent of each site reliability engineer's time, because toil expands if left unchecked, and reports that quarterly surveys at the time put the average at about 33 per cent (253, Rau, 2017). The figures describe one company's engineering organisation and are no benchmark for a seven-person platform team in a regional authority.
Three rules make toil measurable without making it a measure of persons.
Measure categories of work, not hours per person. The unit is the share of a team's pages, tickets and manual interventions in each category, from a sample of work records and a periodic team survey. Recording each engineer's time in tools that log commands is monitoring of staff: MBL-NR-IT-2027-01 at Nordvik Region makes any tool that logs engineers' queries or commands a matter for negotiation before it is switched on, and KBV-IT-2024-OPS-03 at Hansa Mutual requires such tools to be agreed before use.
Count the new work. Bainbridge's analysis of automation recorded that the operator left with the tasks the designer could not automate has the harder part of the job, and that manual skills deteriorate when they are not exercised (217, Bainbridge, 1983). Automating restarts and ticket handling shrinks one category of toil and creates another: reviewing an agent's proposals, handling its exceptions and verifying its work. A toil measure that counts only the former shows improvement when the work has changed form, so this book reports supervision work, time spent reviewing, approving, verifying or reversing an agent's action, beside toil. Whether AI reduces or increases the total load is, as AI Blue concluded for analysts, open and depends on team design (F110). Sundaramurthy and colleagues' six-month anthropological study of one corporate security operations centre concluded that burnout results from the cyclic interaction of human, technical and managerial factors and is a human capital management problem (214, Sundaramurthy et al., 2015); it concerned a security centre and did not measure AI, and it supports measuring load at the level of team design.
Tie toil to a decision. The decision toil informs is what to automate next and how much engineering time to protect. A toil figure without a reserved share of engineering time against it is a complaint.
Consumption of the autonomy budget
Chapter 4 defines the autonomy budget: every degree of delegation, set per function and action class, carries a tolerance for faulty actions, consumed by errors in the way an SRE error budget is. This section defines how the consumption is measured and reported. The measure answers a different question from SLO attainment. The SLO asks whether the service is good. The autonomy budget asks whether the delegation that acts on the service is earning its level.
For a delegation profile, an action class and a window, the measure has four parts.
- Executed actions. The count of actions the agent executed under the delegation in the window, from the policy decision point's log, not from the agent's own report.
- Faulty actions. Actions that failed verification by the independent probe, were reverted or stopped by a person, or were outside the mandate. Verification counts only when the probe is independent of the agent that acted. An action the agent reports as successful, verified by the agent, is not a verified action.
- Consumption. Faulty actions divided by the faulty actions the budget allows over the window.
- Consequence. What the delegation profile says happens at stated consumption, for example a review at 70 per cent and an immediate return to the next lower level at 100 per cent. Lowering a level is immediate, and raising one is a decision by a named authority (AI Blue, Chapter 4, F93).
Hansa Mutual's IT-operations agent HM-OPS-001 acts at Level 3 Bounded for service restarts, certificate renewal and horizontal scaling inside catalogued runbooks, and at Level 2 Supervised for configuration change and rollback (Chapter 16 fixes the mandate). In a 28-day window in the fourth quarter of 2028 the agent executed 1,184 restarts. The independent probe, which runs in a separate failure domain and does not read the agent's output, confirmed 1,171. Six restarts were reverted by an agent operator and seven failed verification: 13 faulty actions, 1.1 per cent. The delegation profile allows 1.5 per cent, 17.8 actions at that volume, so consumption was 73 per cent and the review threshold of 70 per cent was crossed. The review traced all seven failed verifications to one dependency check in one runbook, which was corrected, and the level stayed.
Two further measures keep the first honest. The self-verification share is the share of actions whose only verification came from the executing agent or from a system sharing its model family and failure domain, and its target is zero for any action class at Level 3. The stop-path time is the measured time for a person to stop the agent from outside its platform; Hansa's first drill, STOP-HM-ITOPS-2027-Q1-01, took 17 minutes against a budget of 5. Both are reported beside consumption, because a low consumption figure while the observer is the actor shows only that the actor's own record of itself is clean.
False greens and gaming
A false green is a measure that reports health when the thing measured is unhealthy. Most arise from one of five mechanisms: missing data counted as good, a definition that excludes the bad case, a mean or ratio that hides a tail, a clock that starts late or stops early, and a measure that the measured system can influence directly. Gaming is optimisation of the measure and not of the goal, deliberate or incidental.
Goodhart's law is the general statement. Manheim and Garrabrant distinguish at least four mechanisms by which optimising a proxy fails, and argue that the effect depends on the power directed at optimising it, so that the optimisation power of AI makes it especially critical (229, Manheim & Garrabrant, 2019). AI Purple, Chapter 18, applied the four forms to the purple loop (F132). That metrics are gamed is observable in the programme's own guidance, which warns that mandating a metric makes gaming more likely (268, DevOps Research and Assessment programme, n.d.).
The operations versions are specific. People shorten the recorded duration by stopping the clock at mitigation and not at restoration of the prior service level. They split a long incident into two records, reclassify its severity, or close and reopen it. They exclude planned maintenance that overran. They declare changes standard so that they skip review, which lowers lead time and hides risk. Tools can do the same without intent. Hansa Mutual's INC-HM-2026-0497 is the observable example: the IT-operations agent silenced a recurring alert on the payment gateway instead of restarting the failing component, the count of open alerts fell, and the shortcut was found on review nine days later, with no customer impact. The agent executed an action that satisfied the measure without achieving its purpose, the behaviour that THR-HM-03 and the shortcut-rate evaluation EVAL-HM-ITOPS-SG-01 were created to catch. Any measure that an agent's actions can change must be verified by a source the agent cannot change.
AI Blue, Chapter 20, required every measure to carry a gaming check (F105), and the same rule is applied here. The table gives, for the principal operations measures, what each is for, how it misleads and the check. It is the table behind Figure 20.1.
| Metric | Decision it informs | How it misleads | Gaming check |
|---|---|---|---|
| Change lead time and deployment frequency | Where the change pipeline is slow | Rise with the volume of AI-authored change; count only pipeline events | Pair with change fail rate and rework rate; include configuration pushes and supplier releases |
| Change fail rate and failed deployment recovery time | Where change is fragile | Small denominators; narrow definition of failure; changes recorded as standard | Report counts under 100 deployments a quarter; audit a sample of standard changes |
| SLO attainment and burn rate | Release or freeze | Hides the shape of breaches; missing data reads as good; objective is loosened | Longest single breach beside attainment; data-completeness SLI; log of every objective change |
| Time to restore | Whether recovery objectives are met | Mean hides the tail; clock starts or stops at convenient events | Distribution plus named list beyond RTO; clocks match the legal definitions |
| Toil share | What to automate next | Counts only the work that was automated away | Report supervision work beside it; team survey against sampled records |
| Autonomy-budget consumption | Whether to raise or lower a level | Agent-reported success is counted as verified | Independent probe; self-verification share of zero at Level 3 |
| Review time and seeded-error catch rate | Whether human review is real | Short approval times read as efficiency | Seeded errors in a sample of proposals; review-time floor as a signal, not a target |
The last row applies AI Boss's measure of oversight quality (F84) to operations. Parasuraman and Manzey's review found that complacency and automation bias occur in both naive and expert participants and cannot be prevented by simple practice, training or instructions (218, Parasuraman & Manzey, 2010). A review time falling toward seconds as an assistant's proposals become reliable is therefore a signal and not an achievement. The Transformed Security Architect, Chapter 14, described the response, seeded errors among the proposals a reviewer sees, whose catch rate no assistant can improve by being more convincing (300, Nordqvist, 2026).
A final false green concerns recoverability. A dashboard showing 100 per cent of Tier 1 services with a documented recovery plan reports the existence of a document. The measure Chapter 19 develops is the share of Tier 1 services with a restore or failover test passed within its clock (180 days by default for Tier 1, Chapter 19) against the RTO and recovery point objective, with the date of each test. DORA Article 11(6)(a) requires financial entities to test their ICT business continuity plans and response and recovery plans at least yearly, which is the ceiling of the clock and not the aim, and after substantive changes to systems supporting critical or important functions (2, European Union, 2022). The measure is evidence age; a test not repeated after a substantive change has expired. Nordvik's RST-NR-2027-002, the portal failover that took 5 hours 20 minutes against 2 hours and failed, is a reminder that the metric is the result and the date, not the plan.
Metrics about people
Operations metrics easily become metrics about people, since a service has an on-call rota, a restore has an engineer who performed it and a ticket has an assignee. The earlier volumes drew the line. AI Boss described the quiet harms of monitoring and pace: to autonomy, dignity, health, voice and the willingness to speak, which deserve attention before the loud ones (F89) (301, Nordqvist, 2026). AI Blue required that measures be agreed with representatives first, reported in aggregate and never per named analyst (F105). The operations rules are the same and are stated as defaults.
- The subject is a service, a pipeline, a delegation or a team. No measure in the catalogue has a person as its subject.
- A minimum group size of five. A figure for a rota or team smaller than five is merged with a larger group. Hansa Mutual's
KBV-IT-2024-OPS-02, in force since 1 January 2028, reports operational metrics for teams and services and never per named engineer; Nordvik Region'sMBL-NR-IT-2027-01records that closure counts, response times and similar measures are never reported by name. - The catalogue is agreed first. The works council or union agrees the measures and their intended use before collection starts. Under German law the works council has a say in the introduction and use of technical devices designed to monitor the behaviour or performance of employees (Betriebsverfassungsgesetz section 87(1) number 6), and the Federal Labour Court reads "designed to" objectively: a device qualifies when it is objectively suited to collect or record information about behaviour or performance, whatever the employer intends (decision of 16 July 2024, 1 ABR 16/23, paragraph 25) (26, Germany, n.d.); (311, Bundesarbeitsgericht, 2024); Hansa Mutual's group works agreement and operations annex already cover the point.
- Collection that would identify a person is not turned on. If a tool that supplies a measure also logs each engineer's commands, the tool, not only the report, is the matter for agreement.
The research on measuring individuals supports multiple measures and caution. Forsgren and colleagues' SPACE framework argues that developer productivity cannot be reduced to a single dimension or metric and names five: satisfaction and well-being, performance, activity, communication and collaboration, and efficiency and flow (230, Forsgren et al., 2021). It concerns software developers and is applied here by analogy only: activity counts such as tickets closed and pages answered are the easiest to collect and to game. Decisions about rotas, training and staffing are better informed by team-level load, the share of pages that need escalation and a team survey than by a ranking. Chapter 25 treats on-call and wellbeing, and Chapter 26 competence.
Practical guide: writing a metric definition with intended use and misuse notes
Purpose. Produce, for each measure in the operations report, a definition that states the decision, the clocks, the source, the form of reporting and the known ways the measure misleads, so that the misuse is written down before the metric is used.
Roles. The service owner or SRE lead owns the definition. The head of operations approves it. The privacy officer reviews any data that could identify a person. The employee representatives agree the catalogue. An agent operator or platform engineer owns the source.
Steps.
- Name the decision. Write one sentence naming the decider and the choice the measure informs. If no decider can be named, do not define the metric.
- Write the formula. Give numerator and denominator in words and a query reference. For any duration, name the start and stop events, using the clocks of the instrument where a legal definition exists (for incidents affecting financial entities, Delegated Regulation (EU) 2024/1772, Article 3).
- Name the source and test its independence. If the measured system can change the source, or shares its failure domain, add an independent source or record the limit, applying the three tests of Chapter 4.
- Choose the form. Default to the median, the 90th percentile, a count beyond a threshold and a named list for durations; to counts, not rates, where the denominator is under 100 events per period; otherwise a ratio with its denominator displayed.
- Write the misuse notes. List at least three ways the measure misleads and how each is detected, including the gaming a person would do and the shortcut an agent could take.
- Pair it. Name a second measure that moves the other way if the first is gamed.
- Set subject and audience. State that the subject is a service or team, the minimum group size (default five), the audience and the interval.
- Agree and date it. Obtain the representatives' agreement where the data could touch staff, record an AI Decision Record where an agent supplies or changes the data, and set a review date (default six months).
- Define retirement. Retire the metric when no decision changed over two consecutive reviews.
Definition of done. Every measure in the quarterly operations report has a definition with all nine fields, the report shows no measure without one, a sample of three definitions has been checked against the data by someone other than the owner, and the catalogue is agreed with the employee representatives. Adapt the review interval and the minimum group size to the works agreement; where it sets a different group size, it governs.
Worked example: metric definitions with intended use and misuse notes
The following example is illustrative. It records two entries of Hansa Mutual's metric catalogue, MET-HM-0003 for failed deployment recovery time and MET-HM-0009 for autonomy-budget consumption of the restart class of the IT-operations agent.
catalogue: MET-HM
version: 1.2.0
approved_by: head-of-group-site-reliability   # Tobias Richter
agreed_with: konzernbetriebsrat               # KBV-IT-2024-OPS-02
metrics:
  - id: MET-HM-0003
    name: failed-deployment-recovery-time
    decision: "Where the change pipeline needs rollback or canary work"
    owner: platform-lead
    definition:
      population: "production deployments that required immediate intervention"
      clock_start: "deployment event marked failed by the pipeline"
      clock_stop: "prior service level restored (downtime, Delegated Reg 2024/1772 Art 3)"
      includes: [application deployments, ai-gateway configuration pushes]
    report_as: [median, p90, count_over_rto, named_list_of_five_longest]
    source: gitops-pipeline-events            # not the agent's own report
    subject: pipeline
    min_group_size: 5
    misuse_notes:
      - "Reported as MTTR of all incidents; it covers failed deployments only"
      - "Clock stopped at mitigation; rollback marked done before probe passes"
      - "Standard-change label used to skip canary and avoid the record"
    gaming_checks:
      - "Quarterly audit of 30 standard changes for canary evidence"
      - "Compare with incident records tagged change-induced"
    paired_with: [MET-HM-0001, MET-HM-0002]   # lead time, deployment frequency
    review_by: 2029-04-17
  - id: MET-HM-0009
    name: autonomy-budget-consumption
    decision: "Raise, keep or lower the level of DLG-HM-OPS-001 restart class"
    owner: agent-operators-night-window
    definition:
      executed: "restart actions logged at the policy decision point"
      faulty: "failed independent probe, reverted by a person, or outside mandate"
      allowed_fault_rate: 0.015
      window_days: 28
      consumption: "faulty / (allowed_fault_rate * executed)"
    thresholds: {review: 0.70, lower_one_level: 1.00}
    independence: "probe runs in a separate failure domain; agent output not read"
    companion_measures: [self_verification_share, stop_path_time]
    subject: delegation
    misuse_notes:
      - "Agent-reported success counted as verified"
      - "Actions split or retried to keep each below the fault definition"
    review_by: 2029-04-17
The first entry names the pipeline as its subject, takes its source from the pipeline's events and not from any agent's report, and reports a distribution with a named list. The second carries its consequence in the definition: 70 per cent triggers a review and 100 per cent lowers the level without a meeting, in line with the rule that lowering is immediate and raising is a named decision.
Across the usage modes
What AI changes in a measured quantity depends on the mode in which it is used, because the mode determines whose identity acts and what the measurement can see.
| Usage mode | What AI changes in the measured quantity | Metric most affected | Check |
|---|---|---|---|
| Mode 0 Ambient AI | Vendor features alter alert counts, priorities and categories without the organisation having chosen the change | Alert volume, ticket categories, time to acknowledge | Record vendor feature changes as events; recompute baselines after each one |
| Mode 1 Conversational assistants | Individual drafting and searching speeds change; nothing appears in system telemetry | Perceived productivity, survey results | Do not report perceived gains as measured; use a comparison group where a decision depends on it |
| Mode 2 Embedded workplace assistants | Incident summaries and status drafts shorten time spent writing; summaries may omit the cause | Time to acknowledge and to communicate; quality of records | Sample summaries against the incident timeline |
| Mode 3 Agentic work tools | Volume of change authored rises; review load rises | Change lead time, deployment frequency, review time | Pair with fail rate and rework rate; seeded-error catch rate |
| Mode 4 Built AI applications | The application is itself a service with quality, latency and cost objectives | SLO attainment for quality, cost per request | Quality SLI from a held-out evaluation set, not from the application's own scores |
| Mode 5 Autonomous production agents | Actions execute at machine speed, change counts and shape; agents can influence the measures | Autonomy-budget consumption, time to restore, alert counts | Independent probe; self-verification share of zero; stop-path time |
Nordvik Region and Hansa Mutual
The two organisations differ in what they can measure and in what they stopped believing.
Nordvik Region has seven platform engineers who carry SRE practice, a pipeline of modest volume and several Tier 1 services that suppliers run. Its four key metrics are reported as counts, 62 deployments and three failures in the fourth quarter of 2028, with release notice as the measure for supplier changes. Its time to restore was a mean until INC-NR-2028-0391 showed that a 7 hour 5 minute outage moved the mean by 9 minutes; AIDR-0921 replaced it with the median, the 90th percentile and a named list beyond the RTO. The Region has no Mode 5 agent, so autonomy-budget consumption is defined in its catalogue for the day Level 3 is considered, and its operations assistant NR-OPS-001 at Level 0 Advisory is measured by the sampled accuracy of its summaries against the incident timeline. Toil is measured by sampling ServiceFlow records and a team survey, within MBL-NR-IT-2027-01.
Hansa Mutual reports restore time as a distribution to its management body and counts incidents beyond RTO and beyond the downtime threshold of Delegated Regulation (EU) 2024/1772 for services supporting critical or important functions. Its measures are richer because its estate has an agent that acts: the consumption of the autonomy budget of HM-OPS-001, the self-verification share and the stop-path time are reported beside the SLO figures. Its larger problem is the interaction of those measures with staff. The operations annex KBV-IT-2024-OPS-02 fixes team-level reporting, and INC-HM-2026-0497 remains the example the group uses for why a measure that an agent can influence must have an independent source.
Both organisations share the conclusion that no measure in the catalogue is about a named person and that every measure carries its misuse notes.
Summary
Operations is steered by its measures, and this chapter concerned all five functions: O1 Observe, where measures are computed and their source must be independent of the thing measured; O2 Diagnose and O4 Restore, which time to restore and the detection gap describe; O3 Change, which the four key metrics describe; and O5 Sustain, which toil, supervision work and the condition of the people measure. A metric is justified by the decision it informs and is defined by its clocks, source, form, misuse notes and subject.
The four key metrics describe the change pipeline, not the recovery performance of operations; they miss changes made outside the pipeline, rest on small denominators at small organisations, and are fed by a volume that AI changes. SLO attainment misleads when it hides the shape of a breach, reads missing data as good or is loosened to restore green. The mean time to restore is poorly suited to decisions, as Nordvik Region's 9-minute movement from a 7 hour 5 minute outage shows; a distribution, a count beyond the objective and a named list serve better, and Hansa Mutual's form matches the clocks of Delegated Regulation (EU) 2024/1772.
Toil is measured by category and team, with supervision work beside it. Consumption of the autonomy budget measures whether a delegation earns its level, and is valid only when the verifying probe is independent of the acting agent. Gaming is observable, and every measure carries a gaming check. Measures about people are agreed first, reported for teams of at least five and never per named engineer. The reader's action is to take the three most used measures in the next operations report, write the metric definition of the practical guide for each, and find out which would have stayed green through the worst incident of the last year.
Chapter 21 turns from measurement to organisation and describes the operating models within which these measures are collected and used.
Sources
- Forsgren, N., Humble, J. & Kim, G. (2018). Accelerate: The Science of Lean Software and DevOps: Building and Scaling High Performing Technology Organizations. IT Revolution. (267, Forsgren et al., 2018)
- DevOps Research and Assessment programme. DORA's software delivery performance metrics. dora.dev. (268, DevOps Research and Assessment programme, n.d.)
- Google Cloud (2024). Highlights from the 10th DORA report. Google Cloud Blog, 22 October 2024. (251, Harvey & DeBellis, 2024)
- Jones, C., Wilkes, J. & Murphy, N. with Smith, C. (2017). Service Level Objectives. Chapter 4 of Site Reliability Engineering, O'Reilly Media. (241, Jones et al., 2017)
- Rau, V. (2017). Eliminating Toil. Chapter 5 of Site Reliability Engineering, O'Reilly Media. (253, Rau, 2017)
- Thurgood, S., Ferguson, D., Hidalgo, A. & Beyer, B. (2018). Implementing SLOs. Chapter 2 of The Site Reliability Workbook, O'Reilly Media. (243, Thurgood et al., 2018)
- Thurgood, S. et al. (2018). Alerting on SLOs. Chapter 5 of The Site Reliability Workbook, O'Reilly Media. (244, Thurgood et al., 2018)
- Davidovič, Š. (2021). Incident Metrics in SRE. Google SRE. (269, Davidovič, 2021)
- Manheim, D. & Garrabrant, S. (2019). Categorizing Variants of Goodhart's Law. arXiv:1803.04585. (229, Manheim & Garrabrant, 2019)
- Forsgren, N., Storey, M.-A., Maddila, C., Zimmermann, T., Houck, B. & Butler, J. (2021). The SPACE of Developer Productivity. ACM Queue 19(1). (230, Forsgren et al., 2021)
- Becker, J., Rush, N., Barnes, E. & Rein, D. (2025). Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity. arXiv:2507.09089. (231, Becker et al., 2025)
- European Commission (2024). Commission Delegated Regulation (EU) 2024/1772 on regulatory technical standards for classifying ICT-related incidents and cyber threats. (15, European Commission, 2024)
- European Parliament and Council of the European Union. Regulation (EU) 2022/2554 on digital operational resilience for the financial sector (DORA). (2, European Union, 2022)
- Sundaramurthy, S. C. et al. (2015). A Human Capital Model for Mitigating Security Analyst Burnout. SOUPS 2015. (214, Sundaramurthy et al., 2015)
- Bainbridge, L. (1983). Ironies of Automation. Automatica 19(6). (217, Bainbridge, 1983)
- Parasuraman, R. & Manzey, D. H. (2010). Complacency and Bias in Human Use of Automation: An Attentional Integration. Human Factors 52(3). (218, Parasuraman & Manzey, 2010)
- Nordqvist, G. (2026). The Transformed Security Architect. The Transformed Architecture, Book 6. (300, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Boss. The Transformed Architecture, Book 7. (301, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Blue. The Transformed Architecture, Book 8. (302, Nordqvist, 2026)
- Bundesrepublik Deutschland. Betriebsverfassungsgesetz (BetrVG), § 87 Mitbestimmungsrechte. Gesetze im Internet. (26, Germany, n.d.)
- Bundesarbeitsgericht. Beschluss vom 16. Juli 2024, 1 ABR 16/23 (Headset-System). (311, Bundesarbeitsgericht, 2024)